Author: canutethegreat

  • Horcrux dev log 4: nightly tests, and a NAS login that accepted any password

    Horcrux dev log 4: nightly tests, and a NAS login that accepted any password

    Part 4 in the Horcrux dev log series.

    Backdated: written in November 2026 from git and CI records. Part 3 ended with CI finally running.

    On October 4 a nightly workflow went in that boots an actual VM (CirrOS) and runs real container and CNI network tests. On the 7th a stress suite followed, with workers logging in and hammering the API. Both run on my own runners.

    119 commits in the fortnight. From the Forgejo API for October 1 to 15:

    all workflows: 233 runs (140 success, 68 failure, 18 cancelled)
    ci.yml: 53 success, 43 failure, 13 cancelled
    nightly-realistic-test: 18 success, 17 failure
    nightly-stress-test: 14 success, 3 failure

    About half the realistic nightlies failed. I haven’t broken those 17 failures down by cause, but the boot timeout was one of them. The VM boot deadline was 120 seconds and the runners are TCG-only (no KVM), so a commit on the 8th raised it to 240. On the 15th the commit message says “was never enough”.

    The CNI bugs

    The commit on October 4 says the nightly tests caught two real bugs in CNI and container handling that day, without naming them. My code assumed plugin responses looked one way and real plugins disagreed: cniVersion is camelCase, real plugins leave out empty optional fields, and the stdin payload needed its field names translated as well. Deleting a network also had to be refused while containers were still attached (Oct 5).

    Other fixes from those two weeks, quoted or paraphrased from the commit messages:

    Webhook signatures used Rust’s DefaultHasher, which is not a MAC. Now HMAC-SHA256 (Oct 11). TOTP and backup codes were compared with a plain ==. Now constant time (Oct 11). NAS password checking looked up the user in /etc/shadow and then returned success without comparing anything. “Any password, including an empty one, authenticated successfully for any local user.” That sat under SMB, NFS, FTP and WebDAV auth (Oct 11). Newlines and NULs could be injected into the Kerberos admin scripts and the generated smb.conf (Oct 13). Audit logs believed a client-supplied X-Forwarded-For (Oct 3). A non-ASCII Origin header panicked the CORS layer (Oct 12). NetworkPolicy enforced ports and ignored peer selectors and IP blocks (Oct 9).

    The commit messages don’t say which of these a test caught and which got spotted by reading, so I won’t claim the tests found them. On the 14th the audit job did flag four new RUSTSEC advisories against rustls, and that was a version bump.

    Smaller embarrassments

    “Docker image was building frozen v0.1.0, not HEAD” (Oct 8). Trunk never built main.css, which means the nav dropdowns had no styling at all (Oct 9). The UI hardcoded http://localhost:8006 for API and WebSocket calls, fine if you browse from the server itself and nowhere else (Oct 12 and 15). A VM CPU metric wasn’t divided by vCPU count. Poisoned locks would panic the process (Oct 15).

    What I took from it

    The NAS bypass shipped inside a feature I’d already called complete.

    State on October 15: 53 passing runs against 43 failing on the main workflow and about half the nightlies red. Part 5 is the audit I started on the 16th.

    Design decisions

    Not much is written down for this fortnight. The one clear call is that deleting a CNI network is refused while containers are attached to it (Oct 5).

    Other parts: Part 1, Part 2, Part 3, Part 5, Part 6. The series continues with the latest Horcrux dev log post.
  • Patronus dev log 4: an installer test that failed 57 times in a row

    Patronus dev log 4: an installer test that failed 57 times in a row

    Part 4 in the Patronus dev log series.

    Backdated, written in November 2026 from git and CI records. Part 3 was the restart.

    The installer test

    I wanted a nightly test that installs Patronus into a real VM, with real ZFS, and reboots into it. On October 4 it went in as a workflow. It ran on a Mac build host through UTM, so an x86 guest was emulated on an ARM machine.

    It never worked. From the Forgejo record, October 1 to 15, nightly-realistic-installer-test.yml: 57 failures, 6 cancelled, 0 successes. The overall repo had 249 runs those two weeks: 87 success, 116 failure, 36 cancelled, 10 skipped.

    What the log looks like:

    • Oct 4 and 5: file handoff between the VM and the host. First assumed instant, then polled for 60 seconds, then 180.
    • Oct 5: a serial console capture finally showed where boot stuck. GRUB 2.12 showed its menu, printed “Booting `Linux lts’” and then nothing. I switched the CD-ROM from USB to IDE. The commit message calls it the most likely cause, not a proven one.
    • Oct 5: “retry the live-boot stage – confirmed non-deterministic”.
    • Oct 10: a failing screenshot step turned out to be macOS denying Screen Recording permission (TCC), not a product bug.
    • Oct 13: boot budget pushed to 2700 seconds and the job ceiling to 120 minutes.
    • Oct 14: “pause nightly installer test schedule (TCC emulation can’t finish in time)”, where TCC is a typo for TCG, QEMU’s software emulation.

    Part 5 is what replaced it.

    Bugs that mattered more

    Meanwhile, in the same two weeks:

    • The firewall validated nothing before building nft scripts, so a rule field could inject ruleset text (Oct 12). Fields are now validated first.
    • The web UI’s NAT rules changed an in-memory list and never reached nftables (Oct 12).
    • A literal interface name “any” or “all” was spliced into nft syntax (Oct 13).
    • Captive portal MAC addresses weren’t validated before use in nft commands (Oct 11).
    • Dashboard threat and alert counts were constants (42, 38 and 3) whatever the real state. A commit on the 14th derived them from real data and listed what was still a placeholder: model accuracy, health score and packet rate, “no real ML classifier or packet-rate counter exists yet to back them honestly”.
    • On Oct 13, the container image couldn’t run nft as a non-root user until it got CAP_NET_ADMIN and CAP_NET_RAW on the binary.

    Design decisions

    The commit that replaced the UTM setup says x86 under TCG never booted there.

    State on October 15

    CI on main in the fortnight: 66 successes and 43 failures.

    Other parts: Part 1, Part 2, Part 3, Part 5.

  • Alert fatigue: tuning detections without going blind

    Alert fatigue: tuning detections without going blind

    Part 3 of 3 in the Detection engineering series. Part 1: Logging that actually helps an investigation. Part 2: Writing detections as code: Sigma rules tested against real logs.

    In 2013, attackers inside Target’s network set off malware alerts from a detection tool the company had recently deployed. The alerts reached Target’s security team, and the US Senate Commerce Committee’s 2014 kill chain analysis of the breach concluded they weren’t acted on in time. Roughly 40 million payment cards were stolen. The tool worked. The process around it didn’t.

    That pattern repeats everywhere I’ve looked. When a team gets hundreds of alerts a day and nearly all of them are benign, people learn, quite rationally, that alerts are probably nothing. Then the real one gets the same treatment.

    This is part 3 of the series. Part 1 covered collecting the right events and part 2 covered writing and testing detections as code. Now we have to live with them.

    Measure before you tune

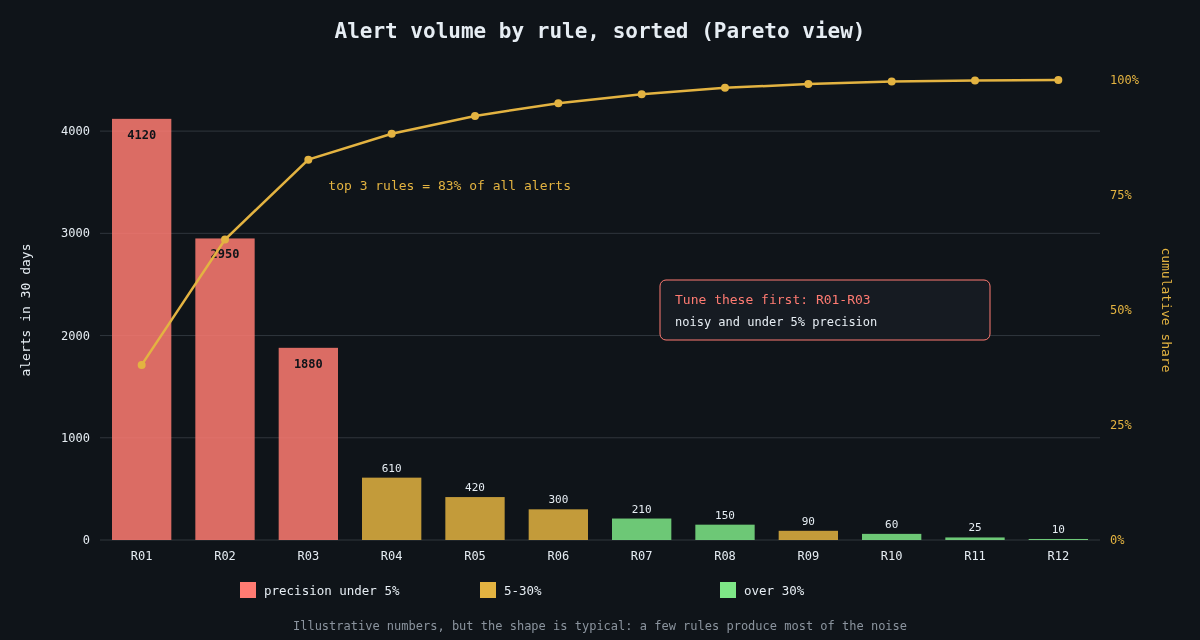
    Illustrative Pareto chart of 30-day alert volume by detection rule, coloured by precision

    You can’t tune what you don’t count. For every rule, track three numbers over a rolling 30 days: how many alerts it produced, how many were true positives after triage, and how long triage took. Precision per rule (true positives divided by total alerts) is the most useful single figure, and it’s almost never on the SIEM dashboard by default.

    That means analysts have to record a disposition when they close an alert. Keep the choices small and honest: true positive, benign true positive (the rule matched what it was meant to, but the activity was authorised), false positive, and needs tuning. The “benign true positive” bucket matters, because an admin running a scanner is not the rule being wrong, and conflating the two leads to deleting good rules.

    When you plot alert volume by rule, you’ll nearly always find that a handful of rules generate most of the noise. That’s good news. You don’t have to fix everything, just the top few.

    Tune narrowly

    The lazy fix for a noisy rule is excluding the whole host, the whole service account, or the whole subnet. Each of those is a hole an intruder can stand in. If your backup server is excluded from the PowerShell rule because its jobs are noisy, then PowerShell on the backup server is now invisible, and backup servers are exactly what ransomware operators go looking for.

    Make exceptions as specific as the evidence allows: the exact parent process, the exact command line or script path, ideally the file hash and the expected account. In Sigma that’s a named filter in the rule itself:

    detection:
      selection:
        Image|endswith: '\powershell.exe'
        CommandLine|contains: ' -EncodedCommand '
      filter_backup_job:
        ParentImage: 'C:\Program Files\BackupAgent\scheduler.exe'
        User: 'CORP\svc-backup'
        CommandLine|contains: 'C:\BackupAgent\scripts\prejob.ps1'
      condition: selection and not filter_backup_job

    If the backup agent is compromised and starts running something else, the filter no longer matches and the alert fires.

    Give every exception an owner and an expiry

    Exceptions accumulate like firewall rules. Nobody remembers why half of them exist, and nobody dares remove them. Store them in the repository with metadata, and let CI enforce it:

    # exceptions/powershell-encoded.yml
    rule_id: 0c4b3a9e-71d2-4f5e-9b8a-6e2d1c7f3a10
    filter: filter_backup_job
    reason: Vendor pre-job script uses encoded commands (ticket SEC-1432)
    owner: infra-backup
    expires: 2027-01-31
    import datetime, glob, sys, yaml
    
    today = datetime.date.today()
    expired = []
    for path in glob.glob("exceptions/*.yml"):
        with open(path) as f:
            doc = yaml.safe_load(f)
        if doc["expires"] <= today:
            expired.append(f'{path}: owner {doc["owner"]}, expired {doc["expires"]}')
    
    if expired:
        print("\n".join(expired))
        sys.exit(1)

    When an exception expires, the owner either renews it with a fresh justification or it goes away. Ninety days is a reasonable default. It’s mildly annoying, and that’s what keeps the list short.

    Change what happens, not just whether it fires

    Not every detection should page a human. A lot of useful signals are weak on their own: a new admin tool on a workstation, a login from an unusual country, a service account authenticating interactively. Individually each one is noisy. Together, on the same host or user within a few hours, they tell a story.

    That’s the idea behind risk-based alerting. Low-fidelity rules don’t create alerts; they add a risk score to the user or host they involve. A separate correlation rule fires when an entity’s accumulated score crosses a threshold, or when signals from several distinct ATT&CK tactics appear together. Splunk documents this approach as its RBA framework, but you can build the same thing in any SIEM that can aggregate by entity over a time window.

    Alongside that, route by confidence. High-precision rules page someone. Medium ones land in a queue that’s worked during business hours. The rest feed risk scores and dashboards. A rule that has never produced a true positive in a year and doesn’t feed anything is a candidate for retirement, but only after you’ve confirmed it can still fire (see the next section), because a rule that never fires might be a rule that’s broken.

    Prove you’re not blind

    Tuning removes alerts. The danger is that you can’t easily see the alerts you removed, or the ones that stopped firing because a log source died. So you need a positive signal that coverage still exists.

    Part 2 described scheduled end-to-end tests: a harmless, known action on a test host that a specific rule must catch within minutes. Run those continuously, track the pass rate per rule, and treat a failure as an incident in the detection pipeline. Combine it with a per-source volume monitor so that a domain controller going quiet raises its own alert.

    I also like a quarterly review of the top 20 noisiest rules and every rule with zero alerts. The noisy ones need tuning. The silent ones need a test proving they still work.

    Watch the humans

    The last metric is the analysts themselves. If one person is triaging 200 alerts per shift, median triage time drops to seconds and the quality goes with it. Track alerts per analyst-hour and the share of alerts closed in under a minute. When those climb, the fix is in the rules, not in telling people to try harder.

    A detection program is healthy when an alert is rare enough that people still feel a small jolt when one arrives. Getting there is mostly unglamorous bookkeeping, and it’s worth every hour.