Tag: Gentoo

  • Horcrux: I broke Docker on purpose and rolled it back from the web UI

    Horcrux: I broke Docker on purpose and rolled it back from the web UI

    Full disclosure: I make this. Horcrux is my Gentoo-based hypervisor, it’s pre-1.0, and this is my notebook for the week.

    Friday night I merged a Boot Environments page into the web UI. The command line tool underneath, horcrux-be, has been around for a while, but you had to know it existed. Now there’s a page that lists every root file system you can boot, the snapshots, and a yellow button that says “Roll back to previous version”. So on Saturday I installed the daily server image into a throwaway VM on one of my lab laptops, put some containers on it, and broke it.

    The setup

    ZFS root, OpenRC, 2 vCPUs, 6 GB of RAM. Three containers made from the Containers page: nginx, redis, and an alpine box that only sleeps. Every row carries a warning that CRIU isn’t installed so container state can’t be saved. It’s printed on all three rows, word for word.
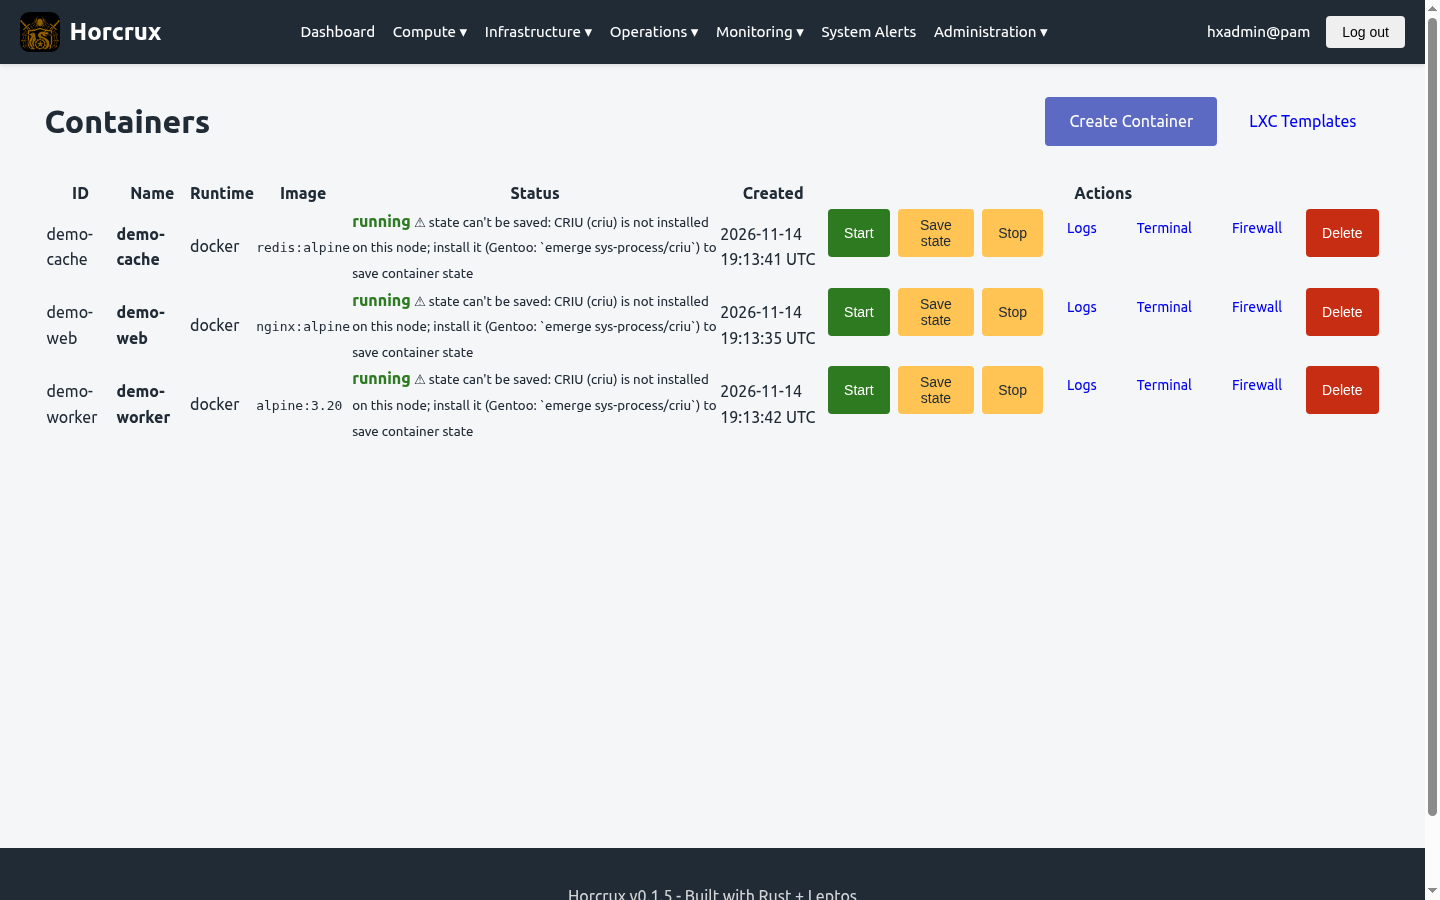
    Horcrux Containers page listing three running Docker containers, demo-cache, demo-web and demo-worker, each with a warning that CRIU is not installed
    The three demo containers before the upgrade.

    Upgrade All takes a snapshot first

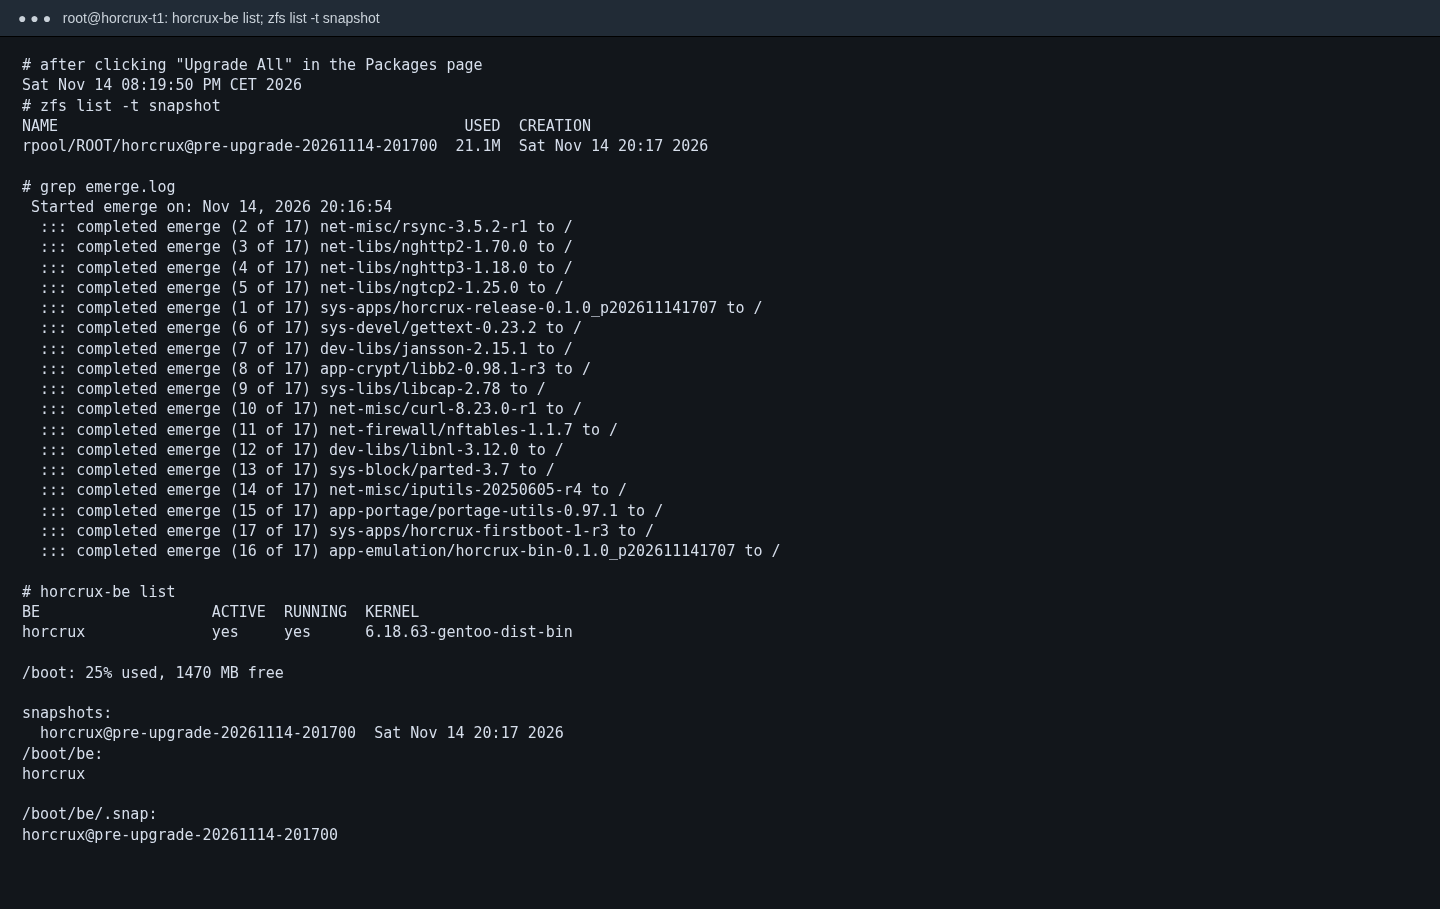
    I hit Upgrade All on the Packages page. Emerge started at 20:16:54 (VM clock; the VM ended up on Berlin time, more on that below) and six seconds later there was a snapshot named horcrux@pre-upgrade-20261114-201700. Then 17 binary packages went in, a new build of Horcrux itself among them, and emerge was done at 20:18:03. 69 seconds. The snapshot was 21 MB at that point.

    The web UI doesn’t take that snapshot. A hook in Portage’s bashrc does, before the first package of any emerge run, at most once every 30 minutes. Emerge from a shell gets one just like the API does.
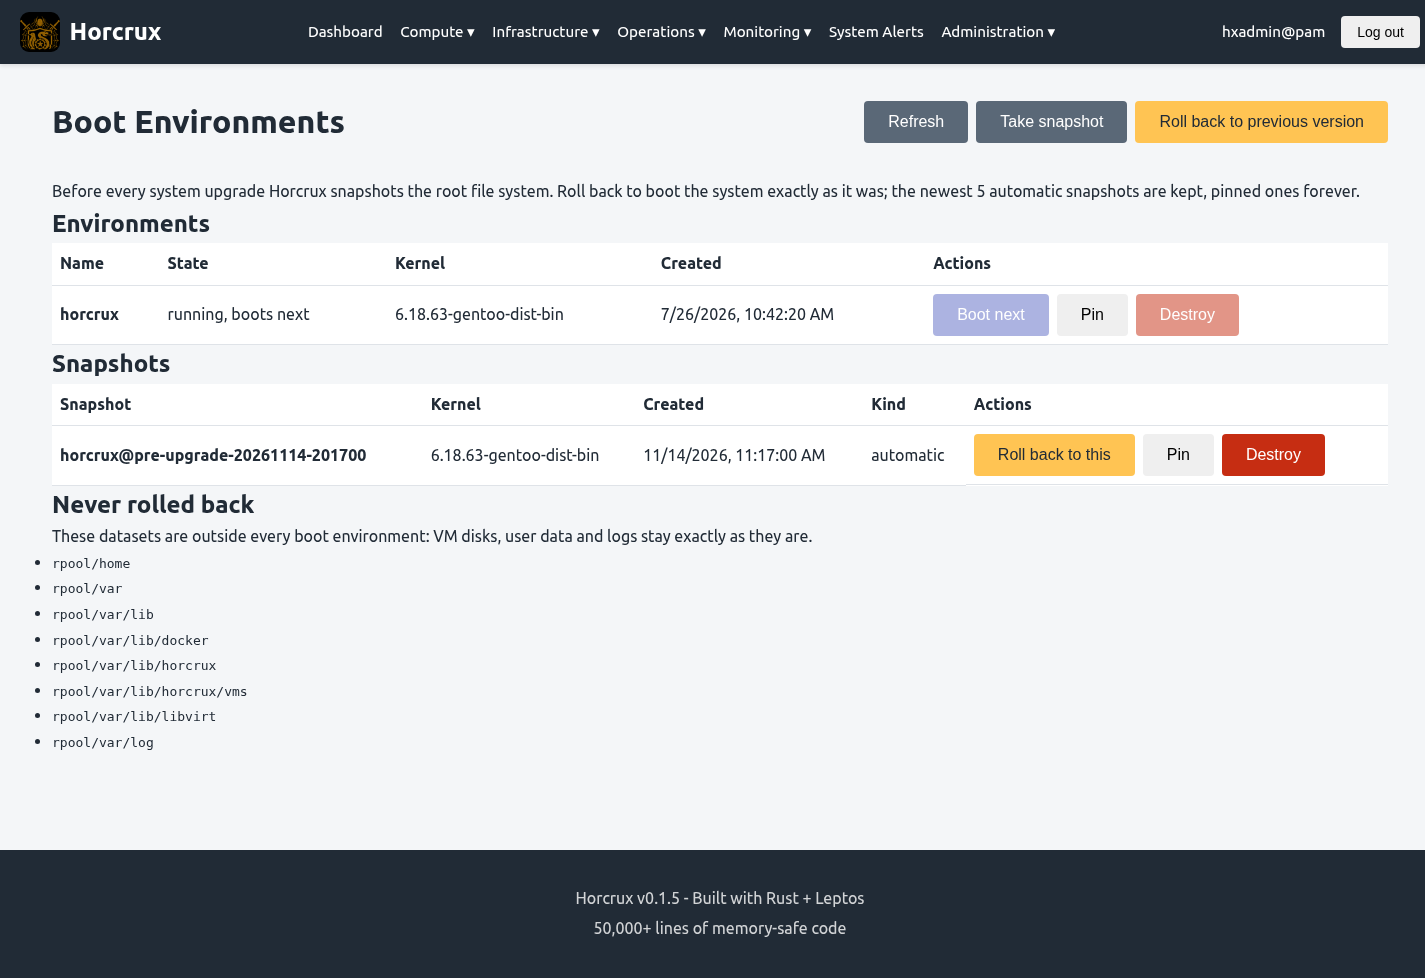
    Horcrux Boot Environments page showing one boot environment named horcrux and an automatic snapshot horcrux@pre-upgrade-20261114-201700
    The snapshot Upgrade All took, on the Boot Environments page.
    Terminal output: zfs list shows the pre-upgrade snapshot, emerge.log shows 17 of 17 packages completed, horcrux-be list shows the snapshot
    The same snapshot from a shell, with the 17 packages emerge installed after it. The VM clock is on Berlin time.

    Then I broke it

    Packages page, search for docker, Remove. The confirm dialog asks “Remove package ‘…’?” and that’s it. Nothing about the four containers running on it (I’d made a fourth one, demo-late, 13 seconds earlier). Six seconds of emerge –depclean and Docker was gone. Reboot, and the Containers page was empty.
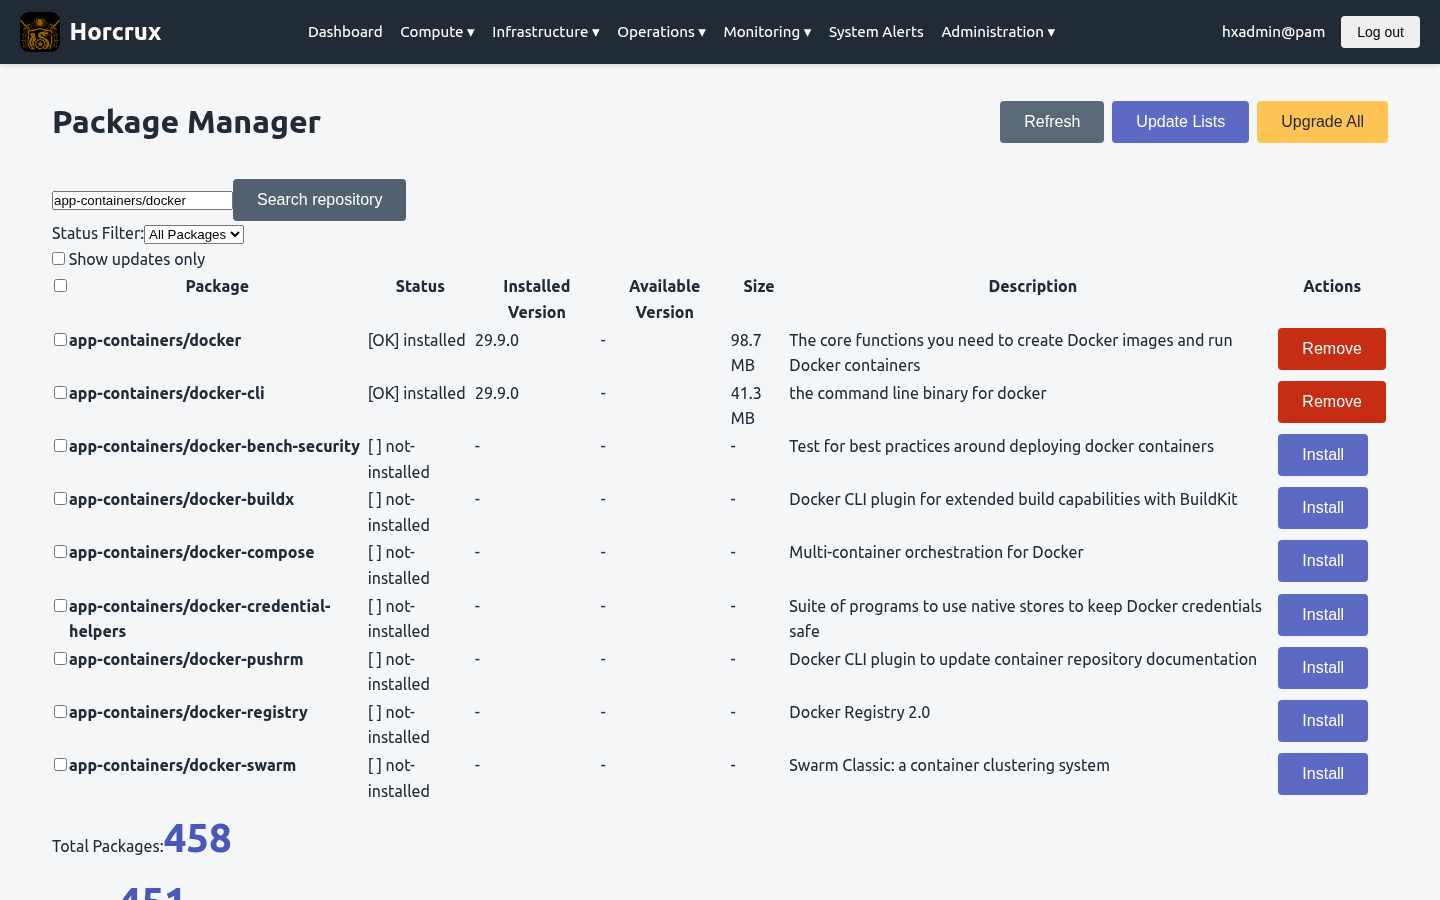
    Horcrux Package Manager page with app-containers/docker installed, version 29.9.0, and a red Remove button
    Docker, one Remove button away.
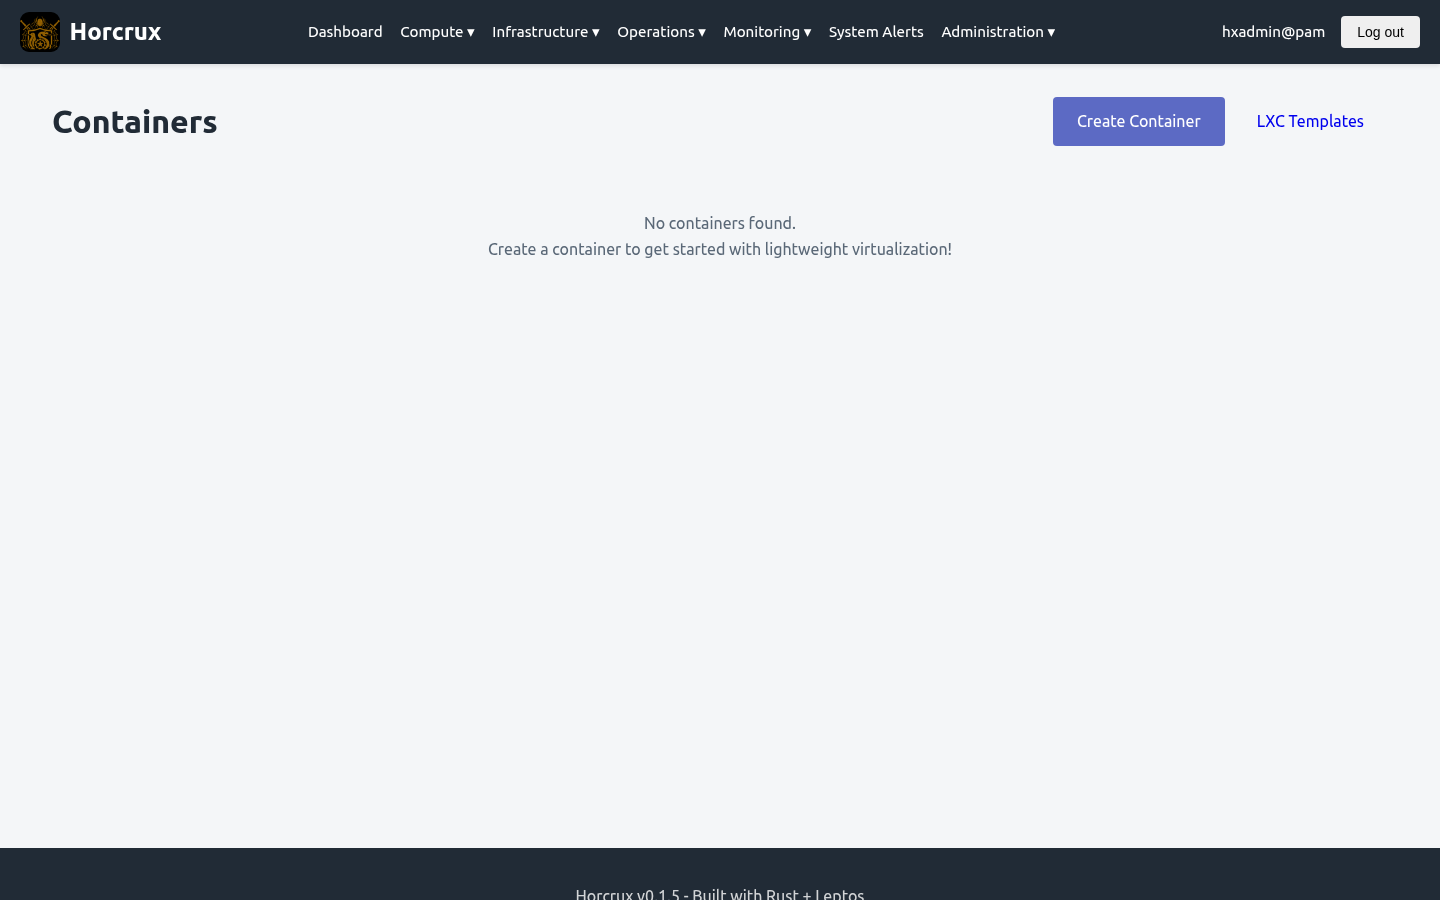
    Horcrux Containers page reading No containers found after Docker was removed and the VM rebooted
    After the reboot: no Docker, no containers.

    Rolling back

    Boot Environments page, “Roll back to this” next to the snapshot. It clones the snapshot into a new boot environment (rollback-20261114-202347), puts back the kernel that was saved with the snapshot, makes it the default in GRUB and tells you to reboot. It doesn’t reboot for you, on purpose, and the environment you’re leaving stays in the GRUB menu. If the rollback itself is bad, you pick the old entry.

    From the empty Containers page to Roll back to this. Pauses between clicks are shortened.

    The kernel came up at 20:25:33 and the API answered 16 seconds later. /proc/cmdline had root=ZFS=rpool/ROOT/rollback-20261114-202347 and dockerd was back. So was the old Horcrux build. The rollback undid the 17 package upgrade too.

    The logs made it through. /var/log is one of the datasets that never rolls back, along with /home, /var/lib/docker, libvirt and the VM disks, so emerge.log still showed the Docker removal after the rollback.
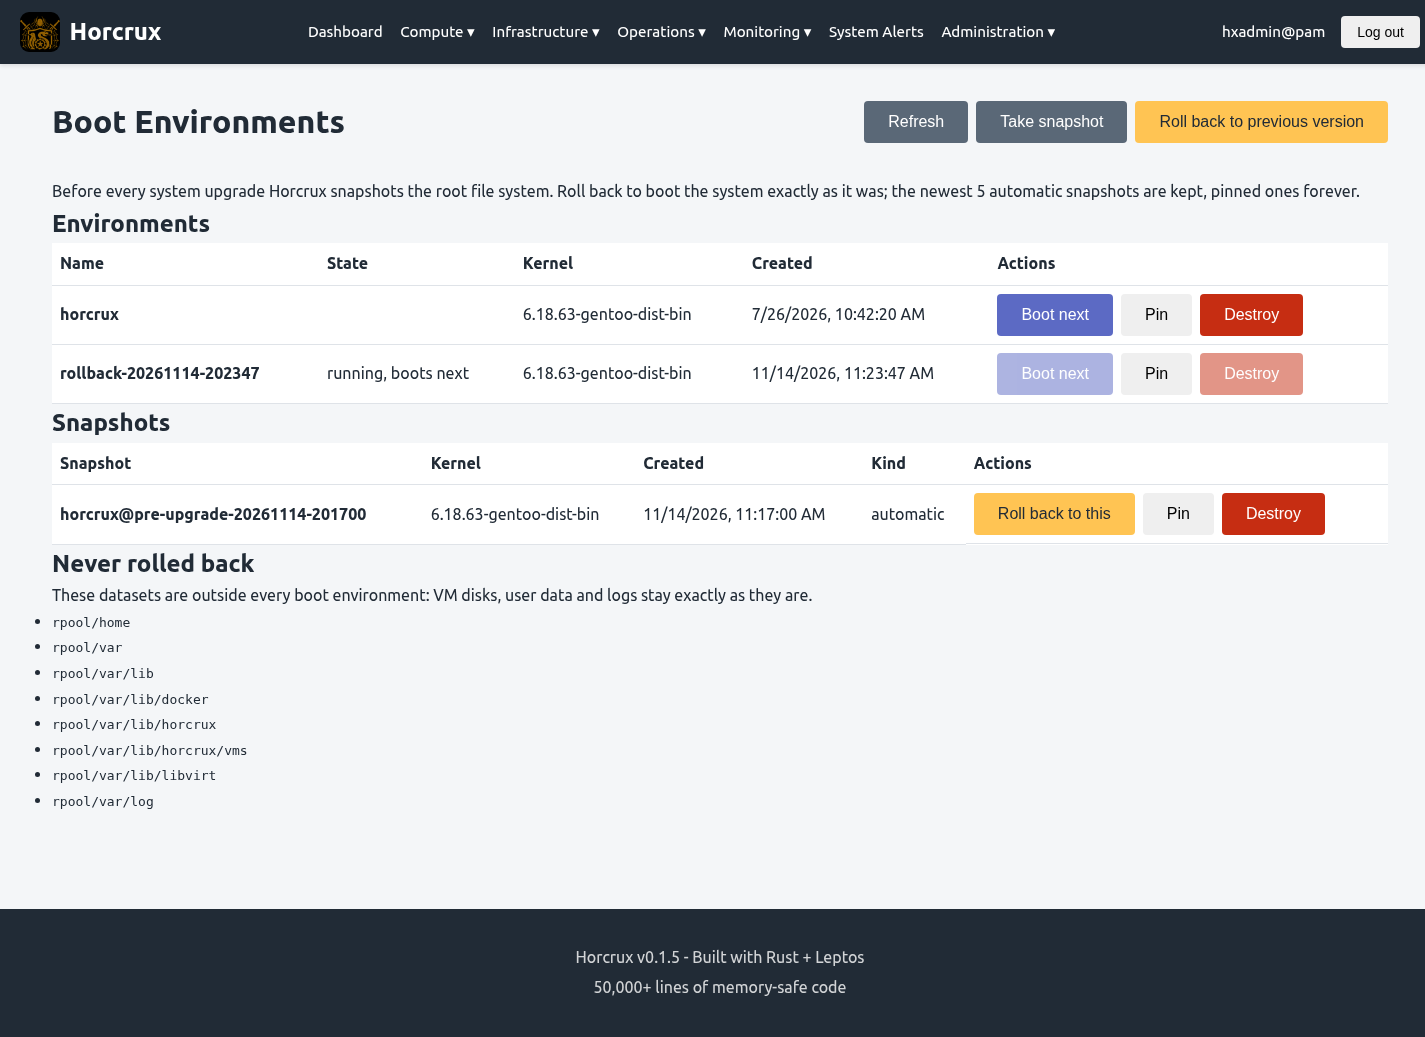
    Horcrux Boot Environments page: rollback-20261114-202347 is running and boots next, the original horcrux environment is still listed, the pre-upgrade snapshot is kept
    Booted into the rollback environment. The original one is still listed and still bootable.

    What doesn’t work (yet)

    • The three containers sat at Exited (255) and nothing started them. I ran docker start by hand and nginx answered.
    • Horcrux is supposed to do that. A service called horcrux-guests resumes guests at boot, and on this install it can’t start at all: “ERROR: horcrux-guests needs service(s) horcrux”. The OpenRC script depends on a service named horcrux, which is what the source build calls the manager. The prebuilt package, the one the ISO ships, calls it horcrux-api. The systemd unit lists both names, so this only bites on OpenRC, and there’s a unit test that checks for the wrong string. No fix yet.
    • The Containers page kept saying “No containers found” with three containers up. The manager started at boot before Docker’s socket existed, logged “Falling back to CLI” and never tried again. Its boot pass handled 0 guests, so it never had a chance to start anything. Restarting horcrux-api made all four show up, but that’s a workaround, the manager should retry or wait for Docker.
    • demo-late, the container made after the snapshot, won’t start: “RWLayer of container … is unexpectedly nil”. Docker’s data is on its own dataset and wasn’t rolled back, and the Docker binary disappeared 13 seconds after that container was created. I don’t know the cause yet.
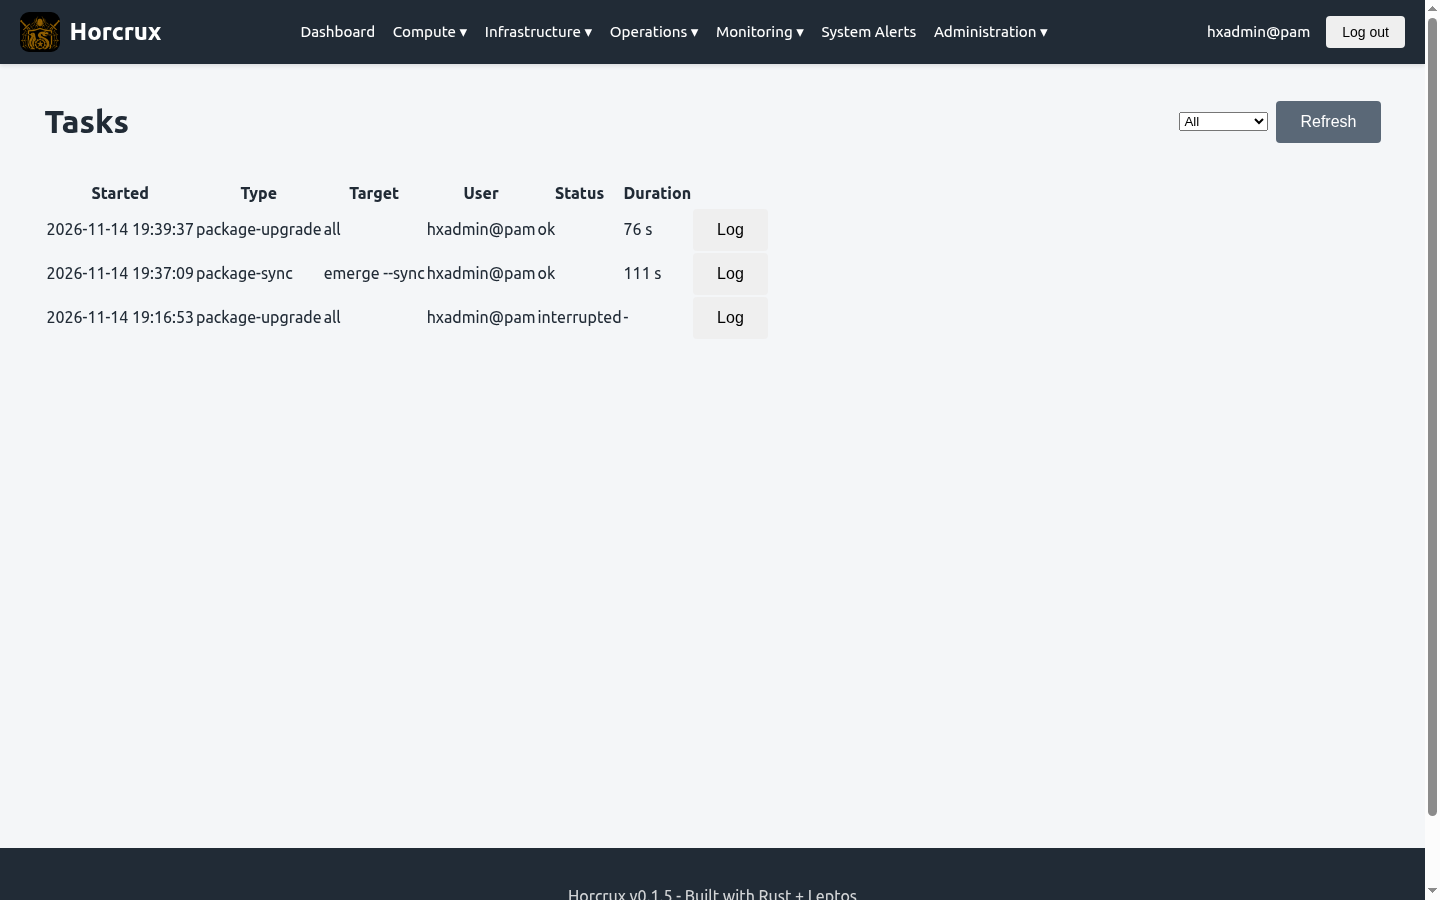
    • The Tasks page shows the first upgrade as “interrupted” with no duration. emerge.log says 17 of 17 and a clean exit.
    • After Upgrade All a green banner says the task started and points you at the Tasks page, then it’s gone in about five seconds and the page looks like nothing happened. The design doc has a banner on the Packages page that shows the snapshot it took. It isn’t built yet.
    • Times don’t line up. Snapshot names use the host clock, the UI uses your browser’s, the logs use UTC. On this VM that was Berlin, Pacific and UTC, and 20:17 in a name meant 11:17 AM on screen. A fresh install also lists its first boot environment as created on 7/26/2026, which is when the image was built.
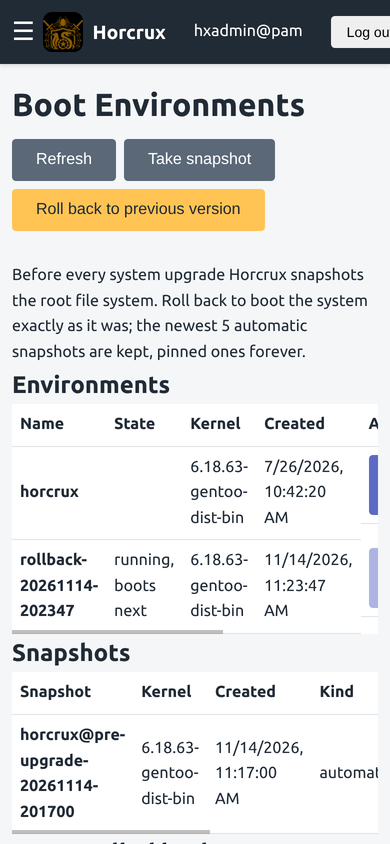
    • On a phone you scroll the tables sideways to reach the buttons, and the Log out button is cut off.
    • After every reboot my browser session was gone, and the tab showed the dashboard with “HTTP 401” errors in the panels instead of the login page. Plus the self-signed certificate warning in every new browser.
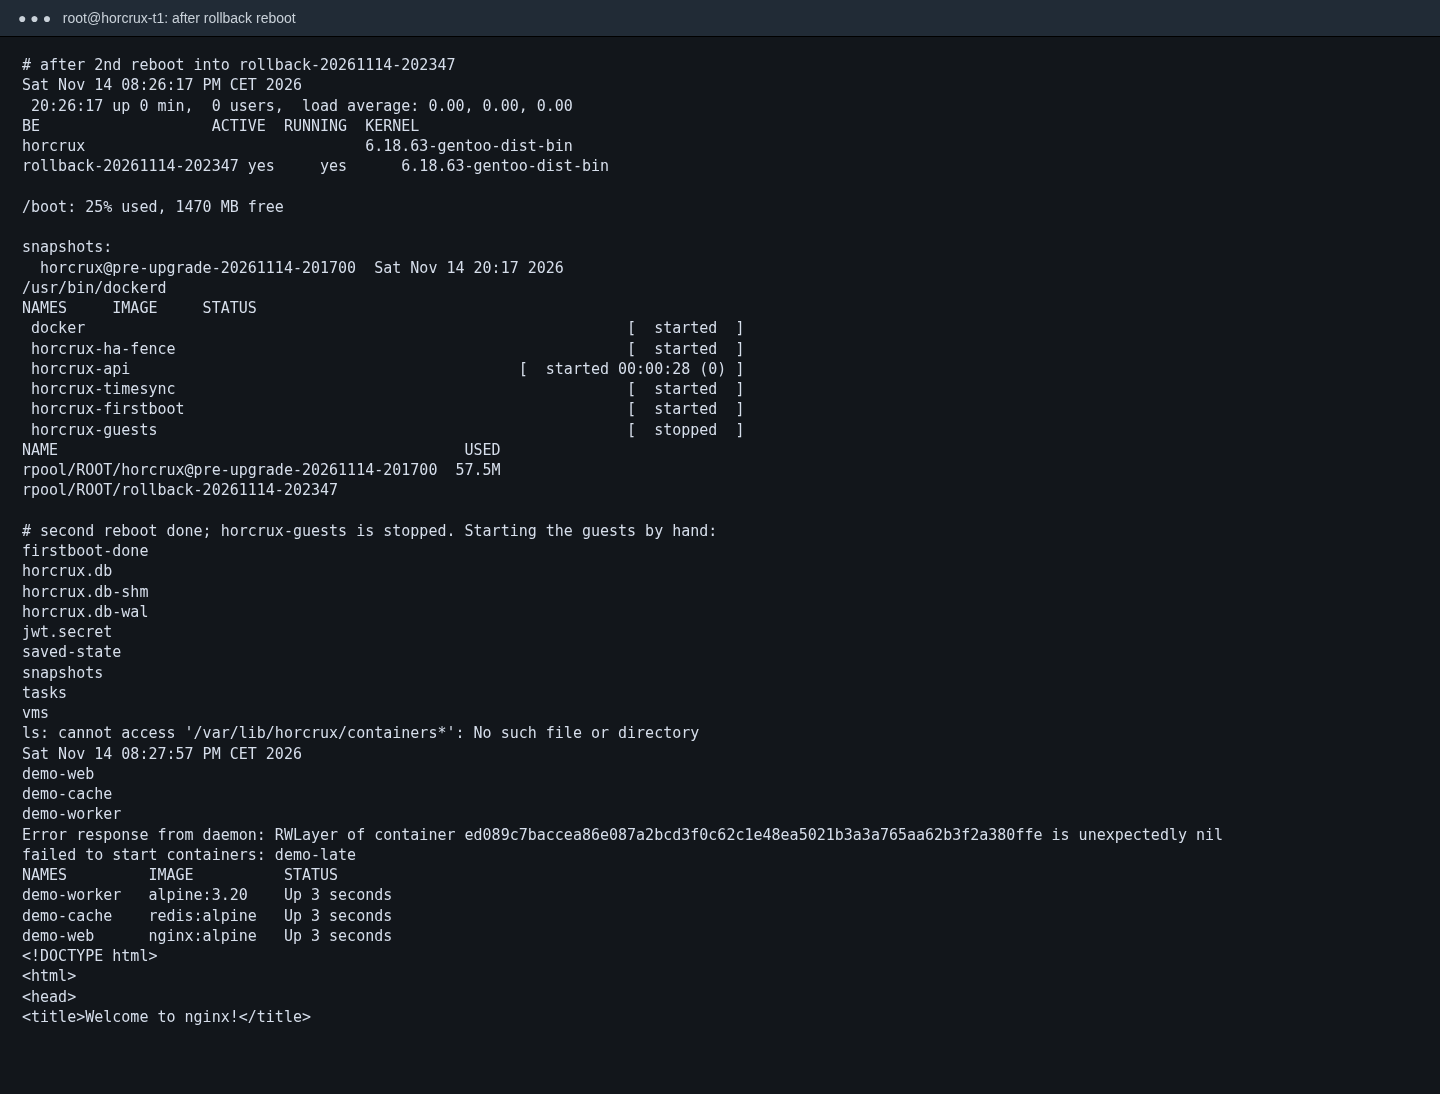
    Terminal after rebooting into the rollback environment: docker is started, horcrux-guests is stopped, three containers are started by hand, demo-late fails with RWLayer is unexpectedly nil, nginx answers
    After the rollback reboot: Docker started, horcrux-guests stopped, containers started by hand, demo-late refusing.
    Horcrux Tasks page: the second package-upgrade ok in 76 s, package-sync ok in 111 s, and the first package-upgrade marked interrupted
    The Tasks page. The bottom row is the first upgrade, which finished fine.
    Horcrux Boot Environments page at phone width, the tables need sideways scrolling and the Log out button is cut off
    Boot Environments at phone width.

    Design decisions

    I wanted NixOS-style rollback in Horcrux, where a bad upgrade means you boot the system as it was before it. My notes on why say “Recovery, bit rot protection, and resilience.”

    ZFS because Gentoo recommends XFS, but ZFS is just superior tech. Horcrux never defaults to ext4, only ZFS or XFS, and boot environments need ZFS.

    I picked Gentoo for the freedom to choose. USE flags are the main reason, hardware specific compiles come second. I’ve run Gentoo since 2006. Every upgrade goes through Portage anyway, so one bashrc hook is enough.

    GRUB, not ZFSBootMenu. ZFSBootMenu fits boot environments better since it reads them straight off the pool. The installer is built on GRUB though (BIOS and EFI, T2 Macs, aarch64, LUKS, mirrored /boot), and GRUB can’t read an encrypted pool, so each boot environment’s kernel sits on a plain /boot and the GRUB config gets regenerated. ZFSBootMenu is the candidate for a later phase.

    Only the root file system rolls back. VM disks, home, logs, Docker and libvirt each get their own dataset. My own design doc says the Horcrux config database rolls back with root, while the installer gives /var/lib/horcrux its own dataset. One of those is wrong, and I haven’t decided which yet.

    Where it stands

    After the rollback I ran Upgrade All again. The page listed 4 upgradeable packages (emerge’s own plan had 17 once dependencies and rebuilds were counted), the task finished in 76 seconds, and a second snapshot showed up, this time on the rollback environment.

    Upgrade All after the rollback, then the Tasks page and the Boot Environments page once it finished. The wait for emerge is cut.

    What’s next

    The guest bugs go first: the horcrux-guests dependency (and the test that checks for the wrong name) and the manager finding Docker when the socket shows up late. The task status after that. Then phase 2 from the design doc: the snapshot shown on the Packages page, an automatic fall back to the previous boot environment after a few failed boots, and moving VM disks out of the root dataset on installs that are older than this.
    https://horcrux.errant.solutions/

  • Horcrux dev log: breaking my own HA cluster on three old laptops

    Horcrux dev log: breaking my own HA cluster on three old laptops

    Part 7 in the Horcrux dev log series. Earlier parts: Part 1, Part 2, Part 3, Part 4, Part 5, Part 6.

    I build Horcrux, and this is my dev log for the week.

    I watched IONIC1K’s video where he hand-builds a Gentoo hypervisor on a $50 Dell R730 because Proxmox 8 to 9 upgrades keep breaking his VMs, RAID and clusters. I was a Debian Developer from 1999 to 2006 and have been on Gentoo ever since, so I’ve lived with both upgrade styles.

    What I was working on

    Horcrux is a Gentoo-based hypervisor with a web UI, written in Rust. It’s pre-1.0 and I’m the only one working on it. The week went into the cluster side: HA, live migration, node replacement and rolling upgrades, tested on three old laptops I keep as a lab. The laptops are wired and slow, which shows timing bugs nicely.

    My bar for HA: every scenario green ten runs in a row, guest back on a surviving node within 120 seconds of a crash, no data loss, never two copies of the same VM running. I’m at 0 of 10.

    What changed this week

    Hard crash failover went from 126 s (over my own limit) to 58.7 s on the first fixed build and 53.6 s on the latest run. Part of that was the manager not starting at boot on a crashed node and not being restarted when it died, so now it runs under supervise-daemon and the QEMU guests survive a manager kill.

    Live migration between two laptops works on hardware now: 62 s the first time and 3 s the second, both directions. I ran a checksummed workload inside the guest and it ended with exactly one copy of the VM and no missing records. In an earlier run a rolling upgrade (drain a node by live-migrating its guest away, upgrade it, next node) took 15, 56 and 47 s per node with the guest running the whole time.

    Partition handling got fixed too. In one scenario the minority node self-fenced at 37 s but the guest on it came back to life about a minute later, so for 34 s there were two copies. After the fixes the double-run time is 0 and the minority fences itself in 10 s.

    Using it on a demo box

    The lab laptops are busy with tests, so for the clips I installed the daily image in a throwaway VM (nested KVM) with demo names. Single node, so none of the cluster stuff is in these.

    ZFS first. The web UI has a Node Shell page, so I did this from the browser: a raidz1 pool across three disks, an encrypted dataset, a snapshot, delete the file, roll back.

    Creating a raidz1 pool, an encrypted dataset, a snapshot and a rollback from the Node Shell page. Real time.

    Next the everyday stuff: make a VM from an ISO in the library, boot it, open the console. The guest is Alpine.

    Creating a VM from an ISO and logging in on its console. The boot wait is cut out.

    And the update. The image has two binhosts configured, mine first and the official Gentoo one as fallback, so an emerge pulls binaries. The world update earlier was 19 packages, 18 of them binary and one pure-Python ebuild with nothing to compile. The clip is a second run in real time: four packages re-installed from the binhost in about 25 s (same versions, since the box was already updated).

    Four packages re-installed from the binhost. Real time.

    Screenshots, since the clips are small:

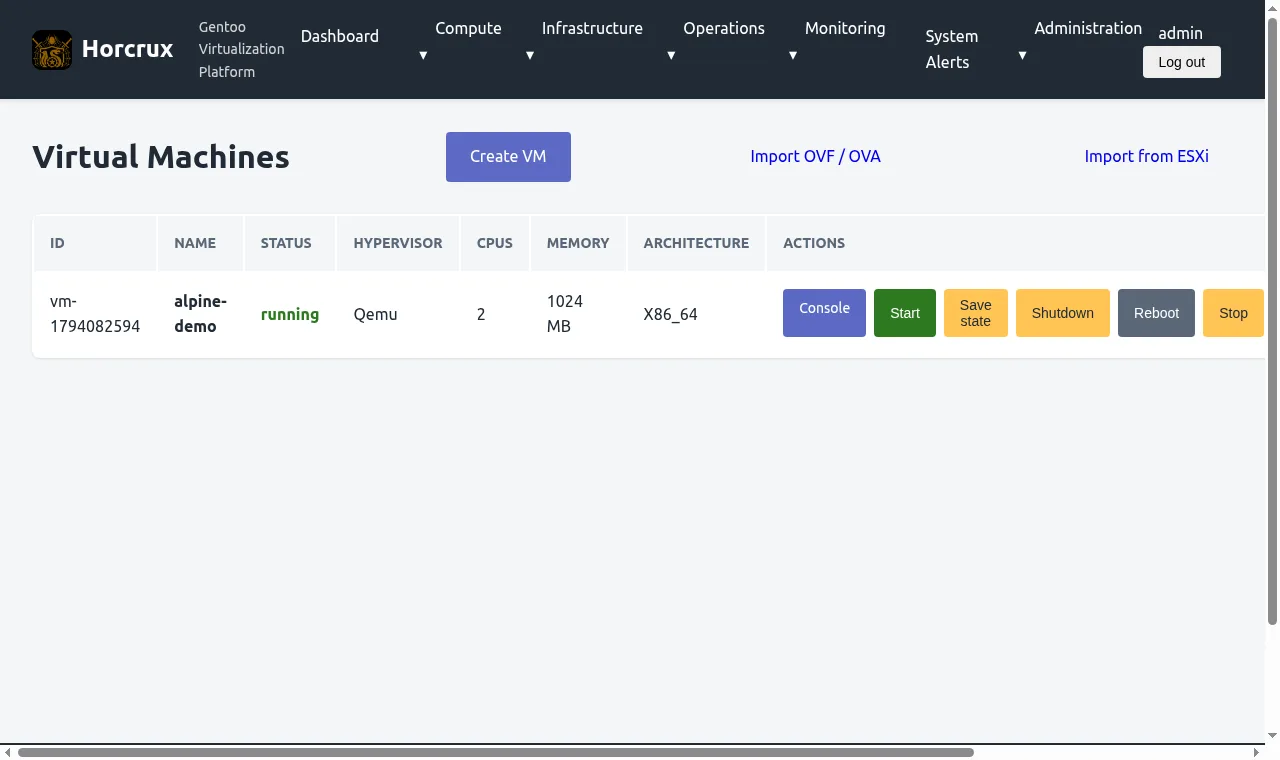
    Horcrux VM list with one running Alpine VM and buttons for console, start, save state, shutdown, reboot and stop
    The VM list with the Alpine guest running.
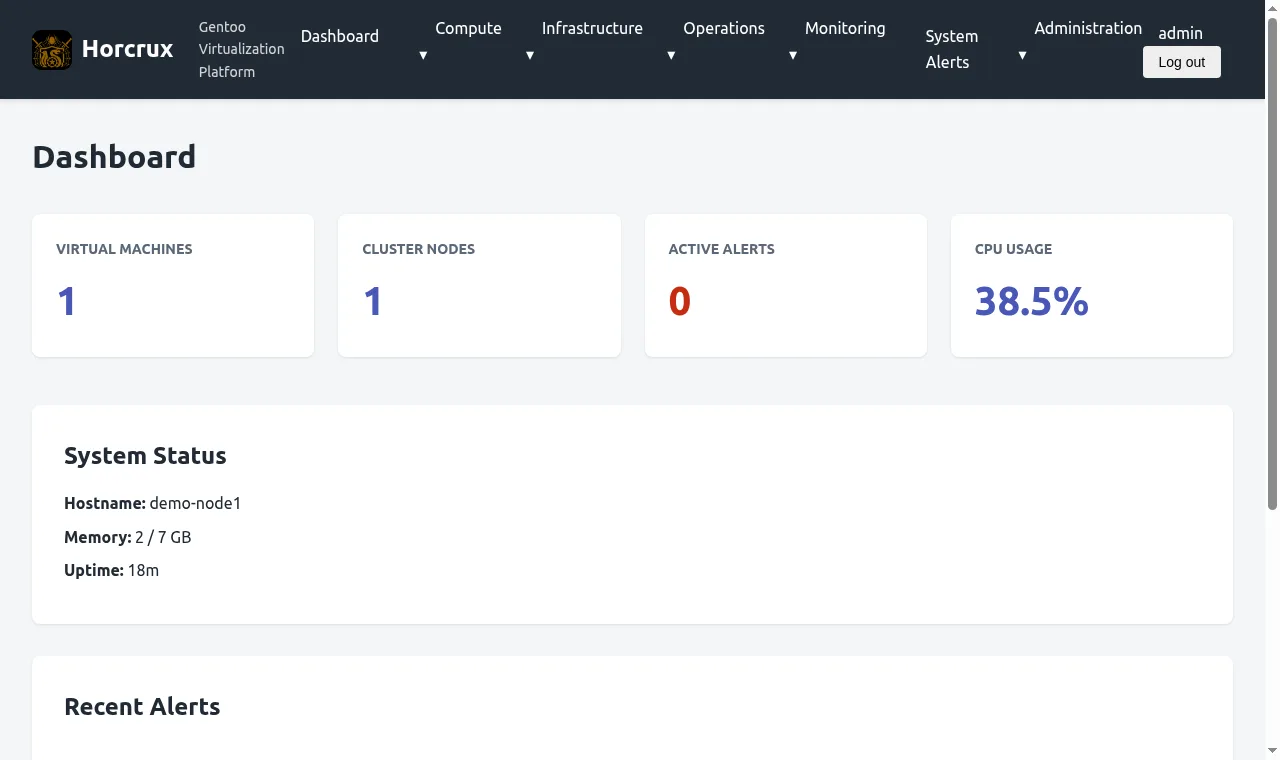
    Horcrux dashboard on a demo node: one VM, one cluster node, no alerts, 38.5 percent CPU
    The dashboard while the VM was booting.
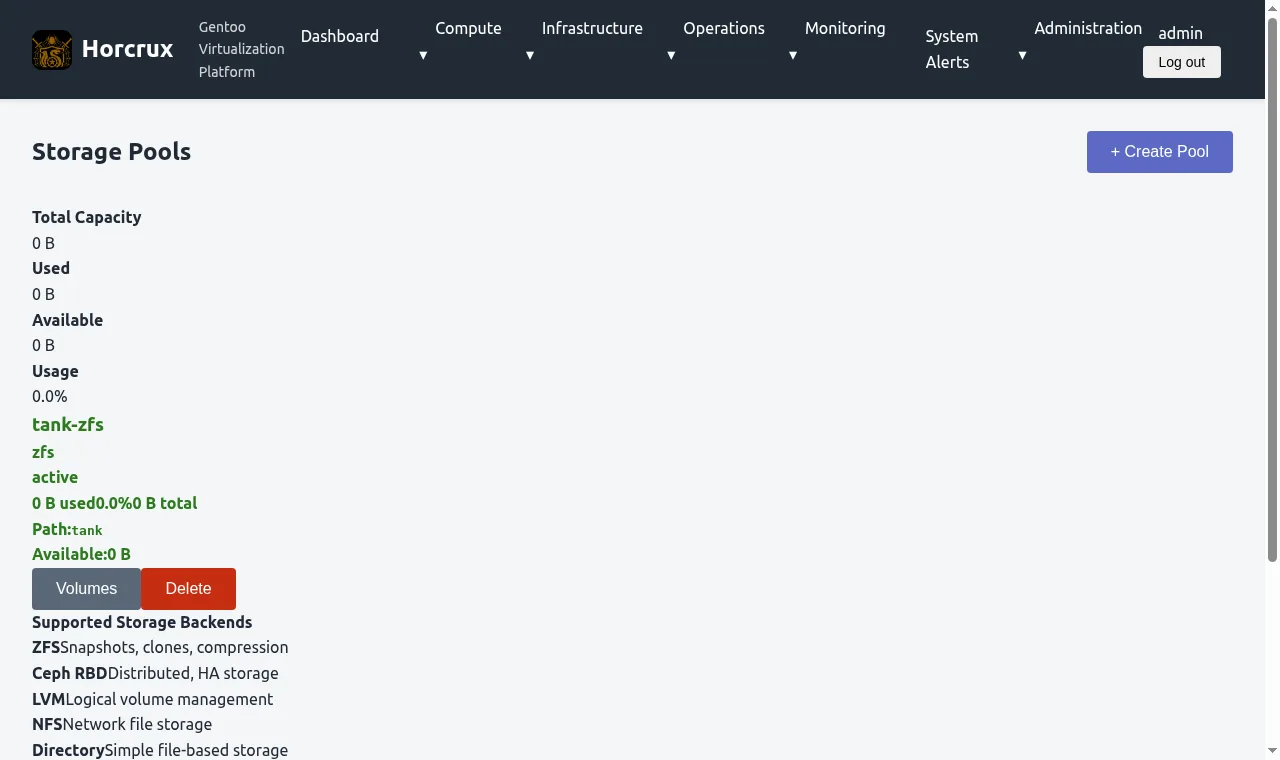
    Storage pools page showing the ZFS pool tank-zfs with 0 B total and 0 B available
    The pool card that says 0 B. The pool is healthy in zpool.
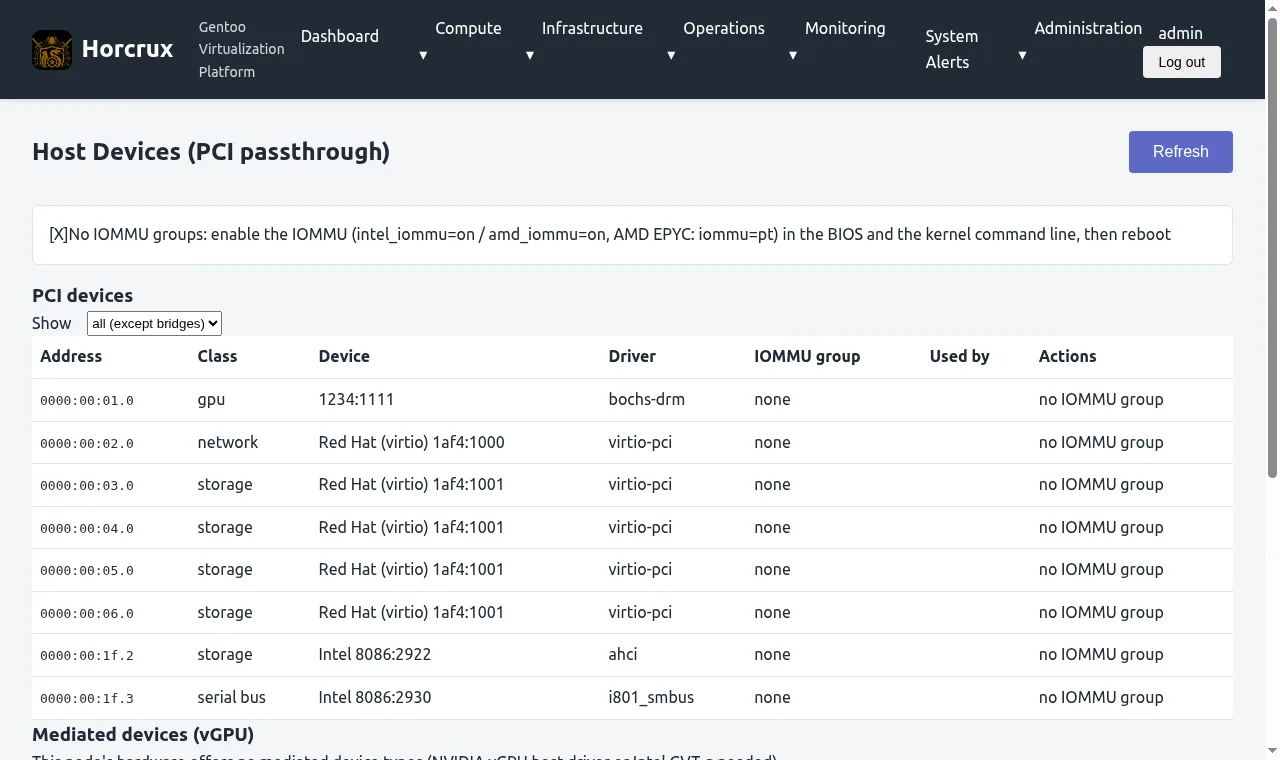
    PCI passthrough page with a message that no IOMMU groups were found in the demo VM
    The passthrough page in a VM with no IOMMU, so nothing to pass through.

    What doesn’t work

    HA is not done. The 3-node suite can’t even run right now: one laptop is gone. I had a scheduler job doing an unattended bare-metal reinstall of the new daily image. It ran 4508 s and the laptop never came back on its address. It answers ping on a new DHCP address but every TCP port refuses, including 22. I don’t know yet whether the installed image lacks the lab sshd or it never left the installer. It needs me to walk over to it.

    Live migration failed after one of my quorum-loss scenarios with “Unable to write to socket: Connection reset by peer”. The cause was HA killing the migration receiver as a stale copy. Fixed and checked on hardware, but the CI run for that branch hadn’t finished when I wrote this, so it isn’t on main.

    Node replacement: when I replaced a node, the other member kept listing the new one as offline forever (“answered by a different Horcrux instance”), because it still pinned the identity of the old install. The fix is on a branch and verified on hardware. Removing a node now also gets announced to the other members.

    Stack stop: a test caught that stopping a compose stack could return success with a container still running 11 s later, when the container list had just been refreshed and overwrote a fresh “running” with a stale “stopped”. Fix is on the branch.

    Wake-on-LAN doesn’t work. Magic packets every 15 s for 10 minutes did nothing from a powered-off state, the laptop only came back at the RTC alarm 642 s later. So the power-off scenario is skipped for now. I think it’s a BIOS setting but I can’t read that from the OS.

    Watchdogs: I assumed the hardware watchdog on one laptop would reset it. It accepted pets and never reset the machine (I stopped the pet process for 7 minutes). So the test machine profile now arms softdog next to the hardware one. Measured resets after stopping the pet: 61 s, 58 s and 26 s on the three laptops. One laptop I called hung for two hours was actually suspended, which I only found by reading syslog.

    Things I hit while recording these clips, on the demo box:

    • I registered the ZFS pool in the Storage page and it shows 0 B total and 0 B available, and the create-VM form doesn’t offer it as a disk target (only the default storage). The pool itself is fine in zpool.
    • I started the update from the web shell and my browser connection dropped partway. The emerge died at package 13 of 19. I re-ran it over ssh and the last six took 1 min 28 s. Not proven that the shell kills its children on disconnect, it’s just what it looked like.
    • The shell page is root. Fine on my own box, but I want to look at that.
    • The GPU page says no IOMMU groups, which is correct for a VM, so I can’t show passthrough. The docs describe it and the API exists, but I haven’t done passthrough on real hardware with a real GPU.
    • Syncing the tree plus a dry-run resolve took 4 min 34 s on that VM before any package moved.
    • Parts of the UI are plain, some pages are barely styled.
    • No systemd image. The images are OpenRC only. The binhost has systemd lanes, but nobody can install a Horcrux ISO with systemd today.
    • No CPU-tuned binaries either, see below.
    • Root install is single disk or two-disk mirror. The raidz1 pool in the clip I made by hand.

    Design decisions

    Gentoo is here for the freedom to choose. USE flags are the main reason, and compiling for specific hardware is a secondary one. The ISOs are OpenRC only because systemd wants to run the world, and the cost is feature bloat.

    The manager and web UI are Rust for memory safety and compile time checks.

    ZFS boot environments and the automatic snapshot before an update are there for recovery, bit rot protection and resilience.

    On HA fencing, Horcrux has fencing agents for IPMI, Redfish, SNMP PDUs and SSH, but the lab machines are old laptops with no IPMI and no switched PDUs, so nothing there can cut another node’s power. What I can test on them is a node that loses quorum stopping its own guests after a timeout, which is the path in the partition results above. The power-off agents haven’t been run on real hardware (the Redfish one has only been tested against a mock BMC).

    Why some of it is the way it is

    ZFS is the default file system, but machines with under 8 GB of RAM get XFS on LUKS instead, because the ZFS cache competes with guests for memory. The root pool can use native encryption (aes-256-gcm, passphrase). The ESP and /boot stay unencrypted because GRUB has to read them. That’s all in the install docs.

    The binhost builds for x86-64-v2, not for any one CPU. Every x86 machine I own, including the old laptops, has SSE4.2, while v3 would break hosts without AVX2 and VMs using a generic CPU model. Separately, a target-cpu=native build crashed on an Intel machine on 2026-10-28, so the image pins v2 now (I haven’t re-checked that on the Intel box yet, see the roadmap).

    The binhost only compiles what the official Gentoo binhost doesn’t already have with matching USE flags, and signs what it publishes. My own number for a server rootfs emerge was 587 s with only the official binhost and 245 s with mine added.

    No default password anywhere: the installer makes you set one, and the web admin password is generated on first boot.

    Where it stands

    Pre-1.0. On my own roadmap checklist none of the nine 1.0 criteria are fully met: five partly, four not at all (last reviewed Oct 28). There’s no CI test that upgrades an installed system’s packages in place and rolls it back at the OS level, though boot environment snapshots exist and the emerge on the demo box took one by itself. The streak counters in the lab say upgrade-test is at 1 of 5, be-rollback-test 0 of 5, cluster-upgrade 1 of 5.

    Next

    Get the dead laptop back and re-run the HA suite with the fixed manager until it’s ten in a row or I find the next bug. Get the migration and rejoin branches through CI and into main. Find out why the reinstalled laptop has no open ports. Try passthrough on a machine with an IOMMU. Fix the 0 B pool card.

    The project page is at horcrux.errant.solutions.

  • Horcrux dev log 6: clustering, an ISO you can install from, and real laptops

    Horcrux dev log 6: clustering, an ISO you can install from, and real laptops

    Part 6 in the Horcrux dev log series.

    Backdated: written in November 2026 from git, CI and my QA ledger. Part 5 was the audit.

    With the basics fixed I moved on to clustering. In five days the log shows an HA supervisor (failure detection, fencing, recovery, self-fencing), cluster create and join, guest save state on host shutdown (QEMU migrate-to-file for VMs, CRIU for containers), draining a node with live moves, SDN zones, Ceph management, deduplicating backups, PCI and vGPU passthrough and a Redfish fencing driver.

    On October 24 live migration got a hard block between AMD and Intel CPUs, and the drain planner never moves a running guest across vendors. Cold migration is still allowed.

    From the Forgejo API for October 22 to November 6: 725 runs, 493 success, 78 failure, 154 cancelled, about 450 commits.

    ha-failover.yml 68 success, 4 failure
    vm-migration.yml 32 success, 0 failure
    guest-power.yml 30 success, 7 failure
    live-iso.yml 21 success, 4 failure, 26 cancelled

    I haven’t checked every cancelled run, but newer pushes superseding a run in progress account for many of them.

    October 27: an ISO that boots

    The December ISO builder never got finished. This one has a different design. A Docker-only builder (Gentoo stage3 plus the official binhost, dracut with dmsquash-live, GRUB for BIOS and UEFI in a hybrid ISO), and a QEMU test that boots it by UEFI and USB and by BIOS and CD, runs an unattended install, reboots into the result and probes the web API. A daily job publishes only if the tests pass. First version: 31 files, about 1,000 lines.

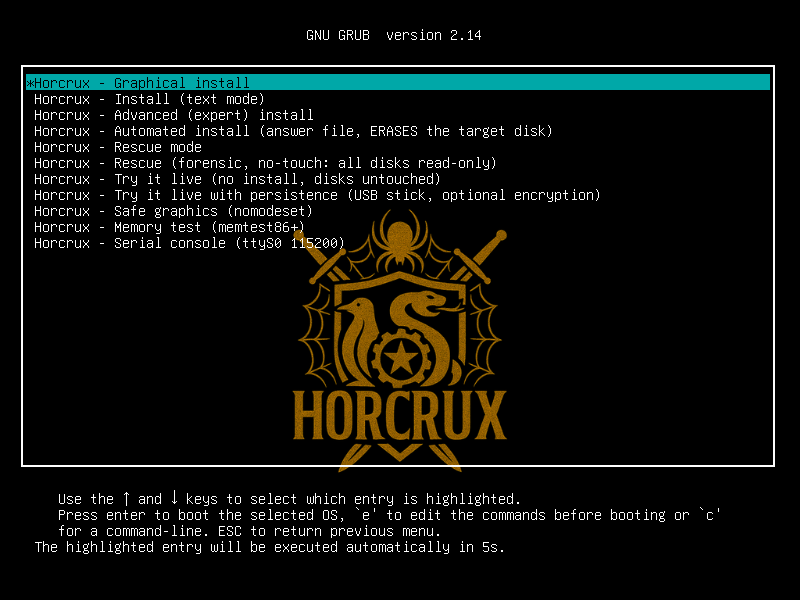
    By the 28th it had a text installer, an answer-file mode, no default password, key-only SSH and aarch64 images. This is the boot menu from that week, taken from the repo’s docs folder at the time:

    The Horcrux installer boot menu in GRUB, committed October 28, 2026
    Boot menu as committed on October 28, 2026 (docs/images/boot in the repo).

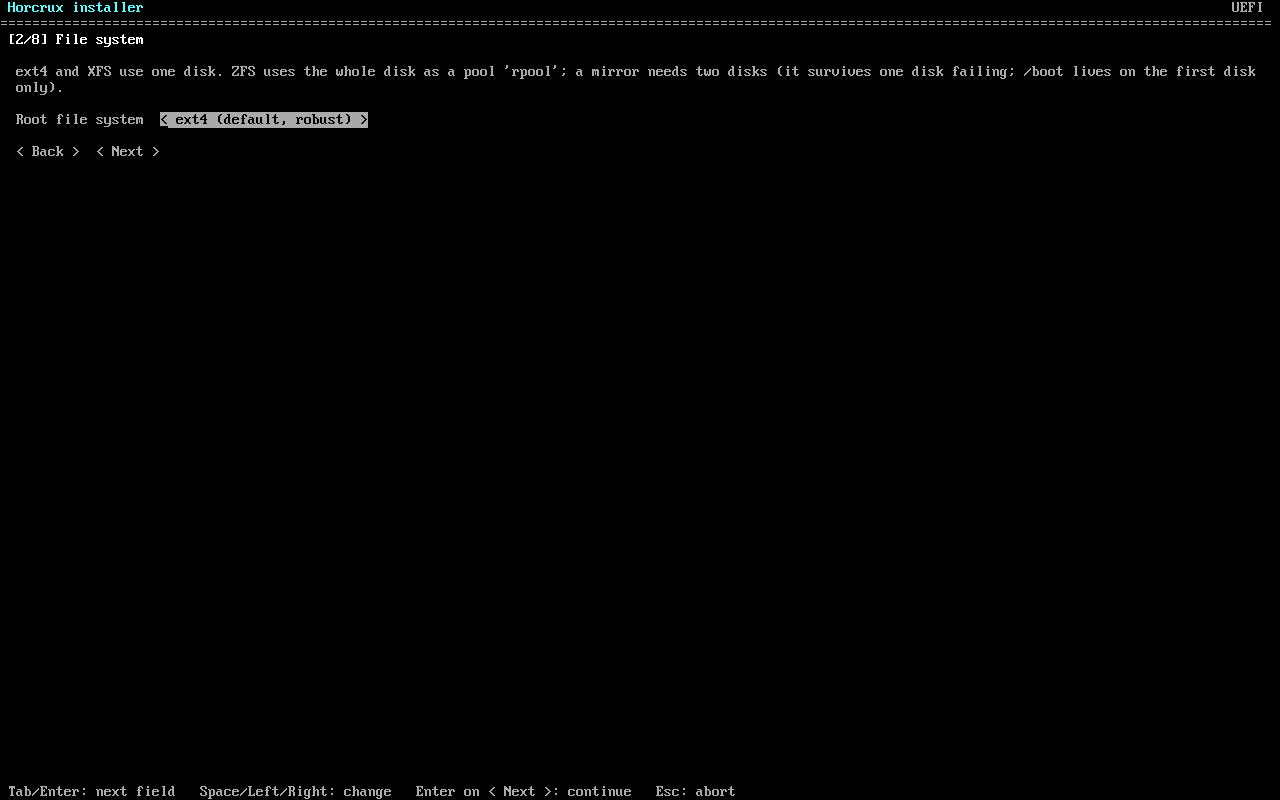
    And the installer’s file system page, committed the same day:

    Horcrux text installer file system page with ext4 as the default
    File system page as committed October 28. The default is ext4, which was wrong and got changed within days.

    The default is ext4. I’d decided ZFS should be the default, with an automatic XFS fallback under 8 GB of RAM or when there’s no ZFS module for the kernel.

    T2 laptops, tablets, encrypted ZFS

    There’s a GNOME desktop edition on top of the server core and hardware profiles for an Apple T2 MacBook and a Surface tablet. The installer learned encrypted ZFS root with boot environments, and hibernate on encrypted ZFS. The initramfs has to resume from the LUKS swap before it imports the pool, because importing first and resuming into it corrupts the pool. A QEMU test does install, passphrase, hibernate, power off, boot, passphrase, same process still running, clean scrub.

    What real machines found

    QEMU didn’t catch several things. The November 3 commits are the list the laptops produced.

    The clock: a live system with a months-off RTC can’t do TLS, so Tailscale and package syncs failed. The installer now writes the hardware clock only from a verified clock, and the tests boot QEMU with -rtc base= months in the past. The size-trimming step on the desktop image kept deleting /usr/include and every static library, so installed systems had no C compiler and ZFS couldn’t rebuild its module on a kernel update. A zfs-kmod from a cached binary package had been built for a different kernel. Plain XFS and ext4 installs didn’t write /etc/fstab, so /boot wasn’t mounted and kernel updates landed on the root filesystem. GDM login started two keyrings. The disk passphrase could be reused as an account password, so the installer now refuses that. And the desktop had apps missing from the launcher because their binary didn’t exist, no sound, dead volume keys, and a Log Out button that did nothing, because the session was split across two D-Bus buses.

    Most of these got a gate in the QEMU suite afterwards (months-off clock, compiler present, module builds, fstab, keyring, password reuse, the desktop session items). On November 3 I also fixed CI reporting green after a failed step (“green-but-failed 8637” in the commit), so some earlier runs looked healthier than they were.

    Where it stands

    This week I moved on to a lab of three old laptops to prove the HA claims. The goal in the lab plan: every scenario of the HA suite green ten runs in a row, failover under 120 seconds, no data loss, never two copies of a guest. As of this writing that’s 0 of 10. The old manager took 126 seconds to fail over after a hard crash, over the limit, and a one-node partition ran two copies of a guest for several seconds. Both are logged as bugs with fixes pending. So I can’t say Horcrux has HA yet. The next post is about that.

    The aarch64 ISO build takes hours under emulation and hit the runner’s time cap on November 6, so it moved to a runner with a longer limit.

    Design decisions

    OpenRC is the only init on the ISOs. systemd wants to run the world, and that comes at a cost: feature bloat.

    ZFS by default, with an automatic XFS fallback when RAM is under 8 GB or the kernel has no ZFS module. The installer shows its reason on the disk page (“XFS instead of ZFS: only 4.0 GB RAM (ZFS wants 8 GB or more)”). I want ZFS boot environments and an automatic snapshot before every update for recovery, bit rot protection and resilience. ext4 is never the default, only a manual choice. Gentoo recommends XFS, and ZFS is just superior tech.

    Encrypted ZFS needs a static grub.cfg and a kernel per boot environment under /boot, because GRUB can’t read an encrypted ZFS pool.

    Hibernate goes to a separate LUKS2 swap partition and not a zvol, because OpenZFS doesn’t support hibernating onto its own zvol and doing it anyway risks the pool. For the Surface XFS layout the notes reject a separate LUKS swap, since it would need a second keyslot or a second prompt.

    Surface tablets get XFS plus LUKS and a light touch desktop, because the docs say a GNOME-class desktop doesn’t fit in 4 GB.

    Server first. On November 3 I wrote down the rule: “it should work on a headless server too, it shouldn’t be a desktop-only OS”. The desktop is a layer on top of a headless core and personal apps live in per-machine layers, not the public images.

    Live migration between AMD and Intel is refused and cold migration is allowed (see Oct 24 above).

    Other parts: Part 1, Part 2, Part 3, Part 4, Part 5. The series continues with the latest Horcrux dev log post.