Author: canutethegreat

  • Prioritising vulnerabilities: CVSS vs EPSS vs CISA KEV

    Prioritising vulnerabilities: CVSS vs EPSS vs CISA KEV

    Part 1 of 3 in the Vulnerability management that works series.

    Every vulnerability programme I’ve seen fail failed the same way. The scanner produced thousands of findings, someone decided “fix all criticals and highs within 30 days”, the backlog grew faster than anyone could patch, and within a quarter the SLA dashboard was a wall of red that everyone had learned to ignore. The problem usually isn’t effort. It’s that the team is sorting by the wrong number.

    This series is about running vulnerability management so it actually reduces risk. Part one is about the sorting, because if you get that wrong nothing downstream matters.

    CVSS measures severity, not risk
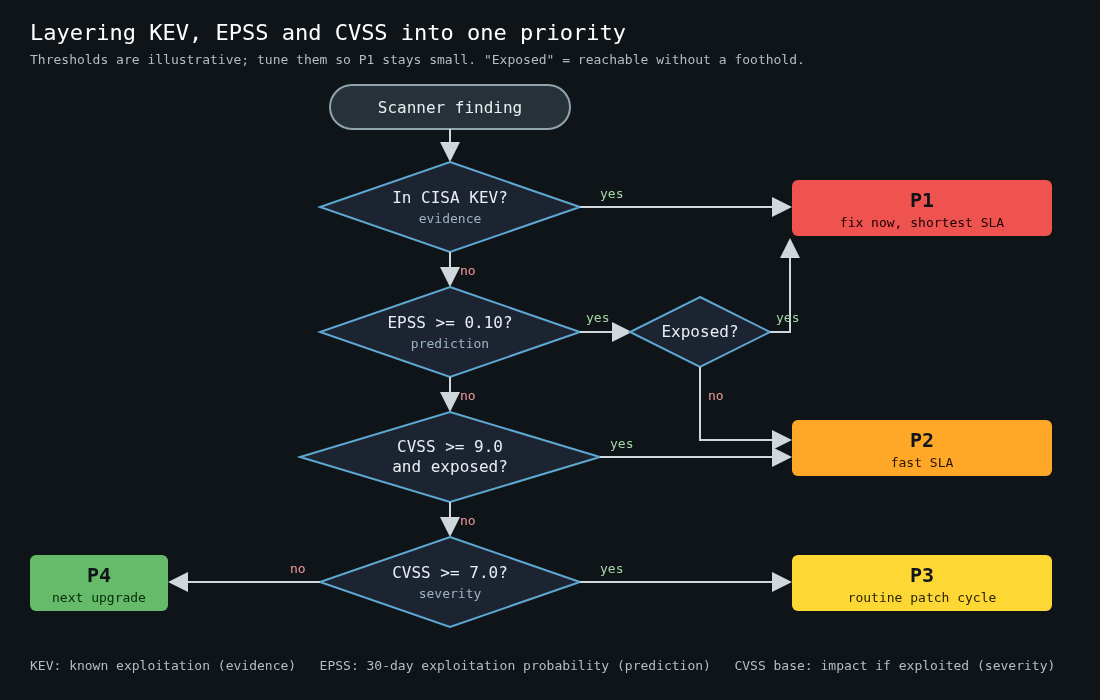
    Flowchart: a scanner finding goes to P1 if in CISA KEV or high EPSS and exposed, P2 for high EPSS or critical CVSS on exposed systems, P3 for CVSS 7 and above, otherwise P4

    The Common Vulnerability Scoring System, maintained by FIRST, is the score everyone knows. A CVSS base score describes the intrinsic characteristics of a vulnerability: attack vector, complexity, privileges required, user interaction, and the impact on confidentiality, integrity and availability. It answers “how bad is this if someone exploits it?”

    It doesn’t answer “will anyone exploit it?”, and the specification says so. The CVSS v3.1 spec states plainly that CVSS measures severity, not risk. Teams use the base score as a risk score anyway, because it’s the column the scanner shows.

    The practical problem is distribution. A large share of published CVEs land at 7.0 or above, so “fix all highs and criticals” means fixing a majority of everything. When half your backlog is priority one, you don’t have priorities.

    CVSS v4.0, released by FIRST in November 2023, tries to address this by making the extra metric groups more visible. There are now Base, Threat, Environmental and Supplemental groups, and the spec asks you to label which ones a score includes (CVSS-B, CVSS-BT, CVSS-BE, CVSS-BTE). The Threat group’s Exploit Maturity metric lets you lower a score when there’s no known exploitation. That’s an improvement in principle. In practice almost every feed you consume publishes base scores only, and the threat data has to come from somewhere else anyway. Which brings us to the other two.

    EPSS estimates likelihood

    The Exploit Prediction Scoring System, also run by a FIRST special interest group, is a model that outputs a probability between 0 and 1 that a given CVE will see exploitation activity in the wild in the next 30 days. It’s trained on observed exploitation telemetry and retrained periodically, with scores recomputed daily. Its inputs include whether public exploit code exists, mentions in security lists, the vendor and the vulnerability type.

    Each CVE gets two numbers: the probability and a percentile. The percentile tells you how it ranks against every other scored CVE. Most CVEs have a very low EPSS probability, which is the whole point. The model is telling you that the vast majority of vulnerabilities never get exploited at all, and it’s trying to tell you which few will.

    You can query it for free:

    curl -s "https://api.first.org/data/v1/epss?cve=CVE-2021-44228,CVE-2023-4863" \
      | jq -r '.data[] | "\(.cve)  epss=\(.epss)  pct=\(.percentile)  as_of=\(.date)"'

    FIRST also publishes the full daily score set as a compressed CSV, which is what you want if you’re enriching a whole scanner export rather than looking up a handful.

    EPSS has limits I’d keep in mind. It’s a prediction about the internet at large, not about your environment. A CVE with a low EPSS score in a product exposed directly to the internet on your perimeter deserves more attention than the model gives it. It also lags. A brand new CVE often scores low on day one simply because the model hasn’t seen any signal yet. And it’s a probability, so treat a score of 0.02 as “unlikely”, never as “safe”.

    KEV is evidence, not prediction

    CISA’s Known Exploited Vulnerabilities catalog launched in November 2021 alongside Binding Operational Directive 22-01. A CVE goes into KEV when three things are true: it has a CVE ID, there’s reliable evidence of active exploitation, and there’s clear remediation guidance such as a vendor patch. BOD 22-01 requires US federal civilian agencies to remediate each entry by a due date CISA sets when adding it, often two or three weeks out.

    KEV is small compared to the CVE corpus, well over a thousand entries against hundreds of thousands of CVEs, and that’s its strength. Every entry is something an attacker has actually used. It’s also available as a JSON feed:

    curl -s https://www.cisa.gov/sites/default/files/feeds/known_exploited_vulnerabilities.json \
      | jq -r '.vulnerabilities[] | [.cveID, .dateAdded, .dueDate, .knownRansomwareCampaignUse] | @tsv' \
      > kev.tsv

    The knownRansomwareCampaignUse field is worth carrying into your tooling. “Known” there means CISA has evidence ransomware operators used it, which in my experience is the single fastest way to get an executive to approve an emergency change window.

    What KEV doesn’t give you is coverage. Exploitation that nobody reported to CISA, or that hit products CISA doesn’t track, isn’t in there. Absence from KEV tells you very little.

    Combining them

    None of these three is a prioritisation scheme on its own. Together they’re pretty good. The way I’d layer them:

    1. In KEV: fix now, on the shortest SLA you have. Someone is using this.
    2. High EPSS and exposed: treat almost like KEV. Exposure means reachable by an attacker who doesn’t already have a foothold, so internet-facing services, VPN concentrators, email gateways.
    3. High EPSS or critical CVSS on exposed systems: the next tier, on a normal fast SLA.
    4. Everything else with a high CVSS: the standard backlog, fixed by routine patching and image rebuilds.
    5. The long tail: fixed when the component gets upgraded anyway.

    As code, roughly:

    def priority(cvss: float, epss: float, in_kev: bool, exposed: bool) -> str:
        if in_kev:
            return "P1"
        if epss >= 0.10 and exposed:
            return "P1"
        if epss >= 0.10 or (cvss >= 9.0 and exposed):
            return "P2"
        if cvss >= 7.0:
            return "P3"
        return "P4"

    The 0.10 cutoff is my choice, not a standard. Pick yours by looking at how many of your current findings land in each bucket. If P1 has more than a few dozen items in a mid-sized environment, your thresholds are too loose, or you have a real emergency and should treat it as one.

    If you want something more formal, CISA’s Stakeholder-Specific Vulnerability Categorization (SSVC) is a decision tree that takes exploitation status, exposure, automatability and mission impact and outputs one of four actions: Track, Track*, Attend or Act. It’s the same idea with more rigour, and it’s easier to defend in an audit than a Python function someone wrote on a Friday.

    The part nobody wants to hear

    The inputs that matter most for prioritisation aren’t in any public feed. Whether a vulnerable package is actually loaded at runtime, whether the vulnerable function is reachable, whether the host is exposed to the internet: that’s your asset inventory and your architecture. A Log4Shell finding in a jar that sits in an unused test directory and a Log4Shell finding in your public login service have identical CVSS, EPSS and KEV values. One of them is an incident.

    So the real first step is tagging assets with exposure and ownership. Once you have that, the public scores do most of the remaining work. Part two looks at SBOMs, which are the other half of knowing what you’re actually running.

    Other parts: Part 2: SBOMs: what they’re actually good for, Part 3: Patch SLAs that teams actually meet.
  • Big-O in Practice: Why Your Database Query Planner Thinks Differently Than You

    Big-O in Practice: Why Your Database Query Planner Thinks Differently Than You

    The gap between asymptotic analysis and real execution

    Chart showing Postgres planner cost crossover between sequential and index scans

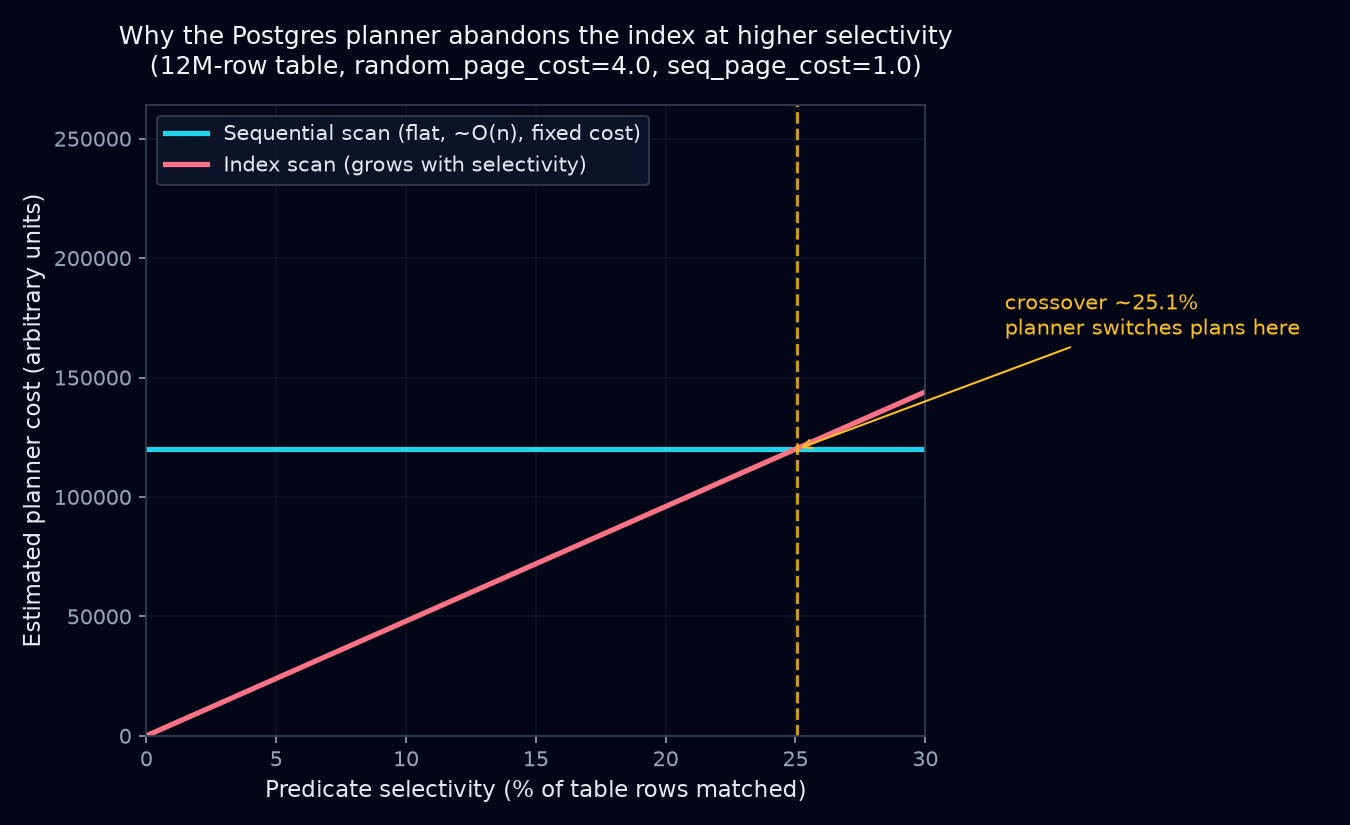
    Big-O tells you how a cost grows as input grows, in the limit, with constants thrown away. That’s the right tool for comparing two sorting algorithms in a CS class. It’s the wrong tool, on its own, for predicting how a database executes a query. A query planner isn’t picking between abstract algorithms on an idealized machine. It’s picking between concrete physical operations (sequential reads, random reads, hash builds, sort buffers) against a measured data distribution, and it prices them in estimated page fetches and CPU cycles, not big-O classes.

    A B-tree lookup is O(log n). A full table scan is O(n). If you stopped there you’d expect the planner to grab the index every time n gets large. Real planners routinely do the opposite, and they’re right to.

    Index scan vs. sequential scan

    An index scan traverses the B-tree, which is cheap (a handful of comparisons), then for each matching entry fetches the corresponding heap page to get the actual row. That’s a heap fetch, and unless the index is covering, you pay for one per match. Each heap fetch is potentially a random I/O: a different disk page, no locality guarantee, unless the table happens to be physically clustered on that column.

    A sequential scan reads the table page by page in physical order. On spinning disks, and even on SSDs behind a page cache, that order benefits from read-ahead and prefetching, which makes it dramatically cheaper per page than scattered random access.

    So the comparison isn’t O(log n) vs O(n). It’s closer to this:

    index_scan_cost ≈ log(n) [tree traversal]
                     + selectivity * n * random_page_cost  [heap fetches]
    
    seq_scan_cost   ≈ n * seq_page_cost

    Postgres defaults random_page_cost to 4.0 against a seq_page_cost of 1.0 (people tune it down to around 1.1–1.5 on SSD-backed systems, but it’s still at or above sequential cost). Selectivity is the fraction of rows the predicate is expected to match. Once that fraction gets large enough, the selectivity * n * random_page_cost term outgrows the cost of just reading the whole table in one pass. The crossover usually shows up in the single-digit percentages of the table, not some rare edge case. That’s why an index that’s fantastic for a highly selective predicate turns actively harmful for a low-selectivity one, and the planner refusing to use it is the correct call, not a bug.

    The planner doesn’t know Big-O. It knows statistics.

    Postgres’s planner is cost-based. It never reasons “index lookup is logarithmic.” It pulls numbers from pg_statistic, populated by ANALYZE: table row count (reltuples), most-common values and their frequencies, histogram bounds for everything else, and correlation between physical row order and column value. From that it computes an estimated selectivity for your predicate, feeds it into the cost formulas above (plus startup cost, CPU tuple cost, CPU operator cost), and picks whichever plan comes out cheapest.

    Big-O describes a trend as n approaches infinity. The planner cares about one specific n, one specific selectivity, and specific hardware cost ratios, and it has to estimate all of that. When stats are stale or a predicate correlates with something the optimizer doesn’t model, those estimates can be badly wrong.

    An illustrative example (not captured live, representative of real behavior)

    Table: orders, 12 million rows, B-tree index on status.

    CREATE INDEX idx_orders_status ON orders(status);
    ANALYZE orders;

    Querying a common status:

    EXPLAIN ANALYZE
    SELECT * FROM orders WHERE status = 'pending';
    Seq Scan on orders  (cost=0.00..305412.00 rows=4812000 width=96)
                         (actual time=0.019..1847.332 rows=4798213 loops=1)
      Filter: (status = 'pending'::text)
      Rows Removed by Filter: 7201787
    Planning Time: 0.112 ms
    Execution Time: 1958.410 ms

    ‘pending’ covers roughly 40% of the table. Even with idx_orders_status sitting right there, the planner skips it and does a full scan. That’s correct: fetching 4.8M heap pages randomly through the index would cost far more than one sequential pass, even though the index path is “O(log n) + k” and the seq scan is “O(n).” The constant on the random-access term swamps the asymptotic advantage.

    Now a selective status:

    EXPLAIN ANALYZE
    SELECT * FROM orders WHERE status = 'chargeback_disputed';
    Index Scan using idx_orders_status on orders
                (cost=0.43..892.17 rows=214 width=96)
                (actual time=0.038..0.291 rows=211 loops=1)
      Index Cond: (status = 'chargeback_disputed'::text)
    Planning Time: 0.098 ms
    Execution Time: 0.324 ms

    Selectivity here is about 0.0018%. The heap-fetch term is negligible, and the index wins by roughly four orders of magnitude in wall-clock time, matching the intuitive big-O expectation, because at this selectivity the random-access constant never gets a chance to dominate.

    Same table, same index, same schema. Only the data distribution behind the predicate changed, and you can’t see that by studying the index structure on its own.

    What to do with this

    Indexes aren’t unreliable and seq scans aren’t secretly fast. Complexity class just isn’t enough to predict real execution cost. Four habits follow from that.

    Run EXPLAIN (ANALYZE, BUFFERS) before arguing about a plan from intuition. ANALYZE without BUFFERS only shows estimated vs. actual rows and time. BUFFERS shows actual page hits and reads, which is where you’ll catch cases where estimated and actual plans diverge because the stats are stale.

    Keep ANALYZE current. Autovacuum handles this most of the time, but bulk loads and fast-churning tables can outrun it, and a bad selectivity estimate produces a bad plan no matter how well you designed the index.

    Don’t assume “it has an index, so it’ll use it.” If a predicate commonly matches a large chunk of the table, a partial index (WHERE status != 'pending') or a different approach entirely (a covering index, BRIN for correlated columns, partitioning by status), is usually the real fix. Forcing index usage with planner hints only treats the symptom.

    When you’re comparing two query shapes, compare their actual costs on your actual data, not their theoretical complexity class. A nested loop join, asymptotically worse at O(n*m), can still beat a hash join on small, highly selective inner relations, because the hash build’s fixed overhead dominates at small n.

    Big-O tells you how a cost scales. The planner has to work out what the cost is for this table, this data and this hardware, and so do you when you’re reading its output. I trust the EXPLAIN output over my asymptotic intuition, because the planner is using a cost function I haven’t memorized and statistics I’ve probably never looked at.

  • Threat modeling with STRIDE for a small team

    Threat modeling with STRIDE for a small team

    Most small teams I talk to think threat modeling is something big companies do with a dedicated security architect, a two-week engagement and a 40-page document nobody reads afterwards. That version exists, and it’s mostly a waste. The version that works for a team of five engineers fits in a 90-minute meeting around a whiteboard and ends with a handful of tickets. STRIDE is the tool I reach for because it gives a room full of people a structured way to ask “what could go wrong here?” without needing a security specialist to lead every question.

    What STRIDE actually is

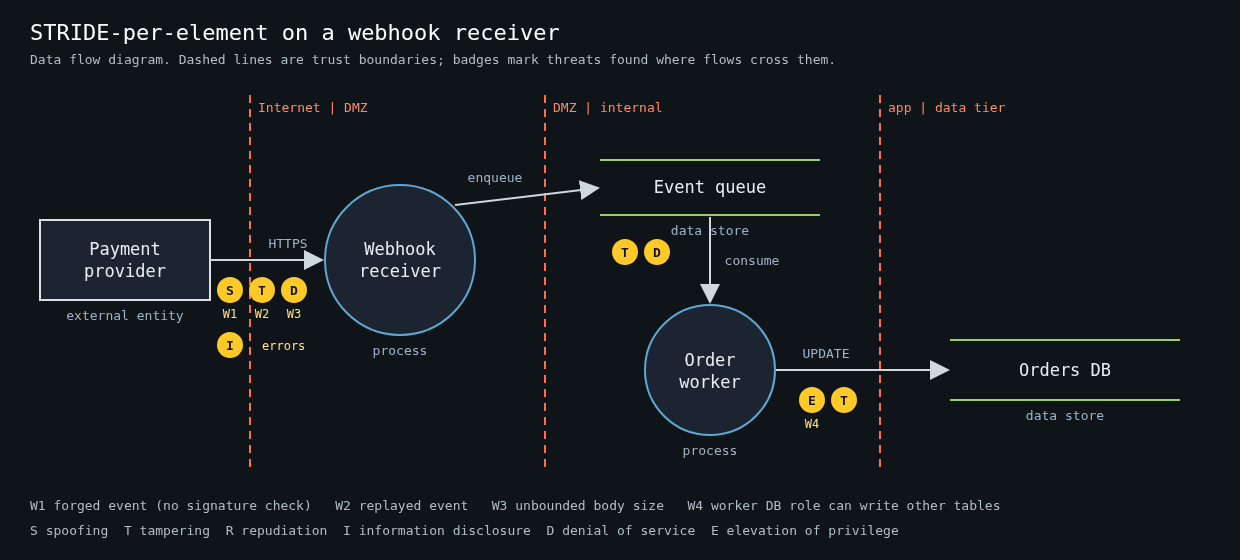
    Data flow diagram of a payment webhook receiver with three trust boundaries and STRIDE threat badges on each boundary-crossing flow

    STRIDE came out of Microsoft in 1999, from Loren Kohnfelder and Praerit Garg, and was popularised by Adam Shostack’s book Threat Modeling: Designing for Security. It’s a mnemonic for six threat categories, each one the violation of a property you want your system to have:

    • Spoofing violates authentication. Someone claims to be a user, a service or a host they aren’t.
    • Tampering violates integrity. Data in transit, at rest or in memory gets modified.
    • Repudiation violates non-repudiation. Someone does something and you can’t prove it.
    • Information disclosure violates confidentiality.
    • Denial of service violates availability.
    • Elevation of privilege violates authorization. A user or component gets capabilities it shouldn’t have.

    That’s it. It isn’t a methodology on its own, and it doesn’t rank anything. It’s a checklist of question shapes. The value is that it stops the discussion from collapsing into whatever the loudest person in the room worried about last week, which in my experience is usually SQL injection.

    Start from four questions, not from the acronym

    Shostack frames the whole exercise as four questions, and the Threat Modeling Manifesto (2020) kept them:

    1. What are we working on?
    2. What can go wrong?
    3. What are we going to do about it?
    4. Did we do a good enough job?

    STRIDE only answers question two. Teams that skip question one end up applying STRIDE to a vague mental picture of “the system”, which produces vague threats like “an attacker could spoof a user”. True, useless.

    So answer question one concretely. Pick one feature or one change, not the whole platform. “We’re adding a webhook receiver that accepts events from our payment provider and updates order status” is a good scope. “Our backend” is not.

    Draw a data flow diagram with trust boundaries

    The diagram is where most of the value comes from, and it should take 15 to 20 minutes. You need four kinds of things:

    • External entities: users, third-party services, anything you don’t control.
    • Processes: your services, workers, lambdas.
    • Data stores: databases, queues, buckets, caches.
    • Data flows: arrows between them, labelled with what moves and over what protocol.

    Then draw trust boundaries, the dashed lines where the level of trust changes. Internet to your load balancer. Your API to the database. Your worker to the third-party API. Your app to the admin interface. If a flow crosses a dashed line, that’s where you spend your time. Flows entirely inside one trust zone rarely produce interesting threats.

    For the webhook example, the boundaries are the payment provider to your public endpoint, your receiver to the queue, and the worker to the orders database. Three crossings. That’s a manageable meeting.

    Walk STRIDE per element

    The variant that works best for small teams is STRIDE-per-element. Not every category applies to every kind of element, and the classic mapping keeps the discussion short:

    • External entities: spoofing and repudiation.
    • Processes: all six.
    • Data stores: tampering, information disclosure, denial of service, and repudiation if the store is a log.
    • Data flows: tampering, information disclosure, denial of service.

    Go element by element along the flows that cross a boundary and ask each applicable question out loud. For the webhook receiver it might go like this:

    • Spoofing: can anyone on the internet POST a fake “payment succeeded” event? Do we verify the provider’s signature, and do we compare it in constant time?
    • Tampering: can a valid event be replayed? Is there a timestamp in the signed payload, and do we reject old ones?
    • Repudiation: if an order flips to paid by mistake, can we show which event did it and where it came from?
    • Information disclosure: do our error responses leak stack traces or internal hostnames to the caller?
    • Denial of service: what happens if someone sends 10,000 large bodies a second? Is there a size limit before we parse JSON?
    • Elevation of privilege: does the worker’s database role need to write to anything except the orders table?

    Every one of those is a concrete, testable question, and most of them are a few lines of code to fix.

    Record threats as tickets, not as a document

    The output of the session is a list of threats, each with a decision. Mitigate, accept, transfer or eliminate the feature. I like a plain table in the repo next to the code, because it gets reviewed in pull requests and it ages with the system:

    | ID | Element            | STRIDE | Threat                                  | Decision  | Ticket   |
    |----|--------------------|--------|-----------------------------------------|-----------|----------|
    | W1 | Webhook endpoint   | S      | Forged event without valid signature    | Mitigate  | PAY-412  |
    | W2 | Webhook endpoint   | T      | Replay of a captured valid event        | Mitigate  | PAY-413  |
    | W3 | Receiver -> queue  | D      | Unbounded body size exhausts memory     | Mitigate  | PAY-414  |
    | W4 | Worker DB role     | E      | Role can write to users table           | Mitigate  | PAY-415  |
    | W5 | Provider outage    | D      | Events delayed for hours                | Accept    | -        |

    Accepted risks are fine. Write down who accepted them. A threat model where everything is “mitigate” usually means nobody was honest about the effort.

    Making it stick on a small team

    Teams rarely fail by modeling badly. They model once at a kickoff and never again, and a few habits help prevent that.

    Tie it to design review. If a change adds a new trust boundary crossing, a new external entity or a new data store with sensitive data, it gets a STRIDE pass. Everything else doesn’t. That keeps it rare enough that people don’t resent it.

    Rotate who facilitates. The facilitator’s job is to keep the group moving through the elements and to stop the session from becoming a design argument. Any engineer can do that after watching it twice, and the person who facilitates tends to start thinking this way in code review too.

    Keep the diagram in the repo as text. A diagram drawn in a SaaS whiteboard is dead the day the meeting ends. Mermaid, PlantUML or OWASP Threat Dragon’s JSON files all diff fine. Microsoft’s Threat Modeling Tool is also free if your team is on Windows and wants STRIDE suggestions generated from the diagram, though I find the generated list too long for a small team to triage.

    Revisit question four. A month after the feature ships, spend ten minutes asking whether any incident, bug report or pentest finding touched an element you modeled. If one did and the model missed it, that’s the most useful feedback you’ll get about your process.

    Where STRIDE falls short

    STRIDE is good at technical threats along data flows. It’s weak on abuse of legitimate functionality, like a referral program being farmed, and on privacy harms, where LINDDUN is a better fit. It also says nothing about likelihood. When a session produces more threats than you can fix, rank them by what an attacker can reach from outside your trust boundaries first, and by what you’d have to explain in an incident report second. That’s crude, and it’s still better than ranking by gut feeling about which bug sounds scariest.

    I’ve watched a five-person team find a missing webhook signature check, an admin endpoint reachable from the public load balancer and a worker with database superuser rights, all in one 90-minute session. Nobody in the room was a security specialist; they drew the thing and asked the questions in order.