Part 1 of 3 in the Detection engineering series.
Most logging in a typical company was set up by developers to debug things. That’s a fine goal, and it produces logs that are close to useless when a security incident lands. Debug logs tell you a function threw an exception. An investigation needs to know which account did what, from where, against which object, and whether it worked.
I’ve sat in enough incident calls to know the moment it goes wrong. Someone asks “when did this start, and what else did that account touch?” and the room goes quiet, because the answer either rolled out of retention last week or was never written down. This post is about avoiding that silence.
Start from the questions, not the log sources
Before turning on anything, write down the questions an investigator will ask. They’re boringly consistent from incident to incident:
- Which identity performed the action, and was it a human, a service account or a token?
- Where did the request come from (source IP, device, user agent, parent process)?
- What was the action and what object did it touch?
- When exactly, and in what order relative to other events?
- Did it succeed?
Every security-relevant event you emit should answer those. If a log line can’t tell you the actor or the outcome, it’s noise for this purpose. A web access log that records the path but not the authenticated user forces you to join it against session tables you may not have kept, so put the user ID in the access log.
Time is the join key, so treat it like one
Investigations are mostly timeline building, and a timeline is only as good as its clocks. Three rules have saved me hours:
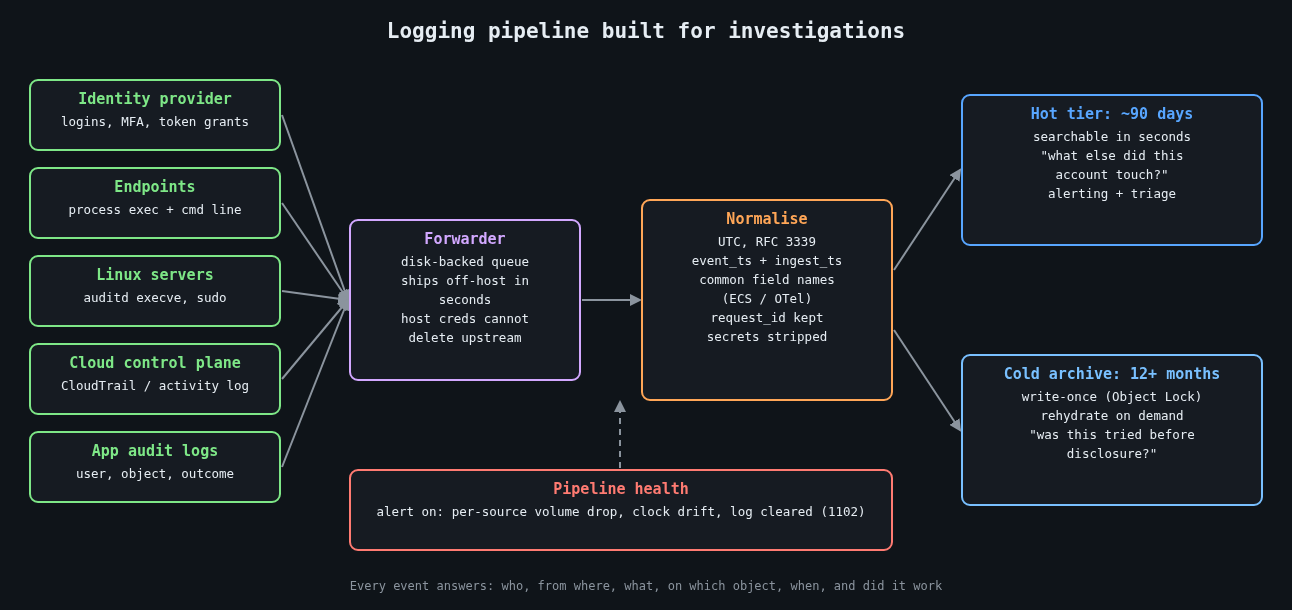
Log in UTC with an explicit offset, in RFC 3339 format. Local time without an offset turns every daylight saving change into an argument. Keep every host synchronised with NTP (chrony is the sane default on Linux) and alert when a host drifts. And record both the event time and the time the pipeline received it, because the gap between them is how you spot a host that buffered logs for an hour or a clock that jumped.
A structured event that actually answers the questions looks something like this:
{
  "ts": "2026-10-13T13:47:12.381Z",
  "ingest_ts": "2026-10-13T13:47:13.020Z",
  "event": "auth.login",
  "outcome": "failure",
  "reason": "bad_password",
  "user": "j.smith",
  "src_ip": "203.0.113.24",
  "user_agent": "Mozilla/5.0 ...",
  "mfa": "none",
  "request_id": "9f2c1e7a-4c1b-4a8e-b0a2-1d5f6c3e8b90",
  "service": "sso"
}
The request_id matters more than it looks. When the same ID flows through your load balancer, API and database audit logs, you can follow a single request across systems without guessing from timestamps.
The events that earn their storage
You can’t log everything forever, so spend the budget on events that show up in nearly every investigation. Authentication, both successes and failures, comes first. Privilege changes (group membership, role assignments, new API keys, sudo) come next. On endpoints and servers, process execution with full command lines is the single most useful source I know of. On Windows that means event 4688 with the “Include command line in process creation events” policy enabled, or Sysmon event ID 1. On Linux, auditd can record execve calls:
# /etc/audit/rules.d/50-exec.rules
-a always,exit -F arch=b64 -S execve -F key=exec
-a always,exit -F arch=b32 -S execve -F key=exec
-w /etc/sudoers -p wa -k sudoers
-w /etc/sudoers.d/ -p wa -k sudoers
Execve logging on a busy build server is loud, so measure the volume before rolling it out everywhere. Config changes to cloud accounts (CloudTrail, Azure activity logs) and data access on your most sensitive stores round out the list.
Then log the logging. Windows event 1102 means the security log was cleared. A sudden drop in event volume from a host usually means an agent died, a disk filled up, or someone stopped the service on purpose. All three deserve an alert.
Retention is a decision, so make it on purpose
Default retention settings were chosen by whoever priced the product, not by your threat model. Mandiant’s M-Trends 2024 report put the global median dwell time at 10 days for 2023, and a median hides a long tail of intrusions discovered months later.
Log4Shell is the example I keep coming back to. CVE-2021-44228 went public on December 9, 2021, and Cloudflare later reported seeing exploitation attempts as early as December 1. Teams with seven days of searchable logs couldn’t answer the most basic question, which was whether anyone had tried this against them before the disclosure.
The US federal baseline in OMB memo M-21-31 asks for 12 months of active storage and a further 18 months in cold storage for most log categories. You don’t need to copy that exactly, but it’s a useful reference point when someone suggests 14 days is plenty. A two-tier setup works well: a few months hot and searchable, a year or more in cheap object storage that you can rehydrate when needed.
The 2023 Storm-0558 intrusion into Microsoft-hosted email made the cost of missing logs very public. The US State Department spotted it because it had access to the MailItemsAccessed audit event, which at the time came with a premium licence tier. Many other affected organisations didn’t have that event at all. Microsoft later expanded default logging, but the point stands: find out which audit events your SaaS providers keep behind a paywall before you need them.
Make the logs outlive the attacker
An attacker with root on a box can edit its local log files, so local logs are a convenience, not evidence. Ship events off the host within seconds, to a system that the host’s own credentials can’t modify or delete. For the archive tier, write-once storage such as S3 Object Lock removes the “delete the evidence” option entirely, including for a compromised admin account if you use compliance mode.
Keep the pipeline’s buffering in mind too. A forwarder with a small in-memory queue will drop events during exactly the network trouble an incident tends to cause. A disk-backed queue costs very little.
Things you should not be logging
Secrets, session tokens and passwords should never land in a log. The classic leak is a failed login where the user typed their password into the username field, so be careful about logging submitted usernames verbatim on failure paths. Bearer tokens in URLs end up in access logs and proxy logs, which is one more reason to keep them in headers.
Log4Shell also taught a second lesson: the logger itself parses what you hand it. Treat attacker-controlled strings as data, keep logging libraries patched, and prefer structured fields over string interpolation.
Test it before you need it
Pick an incident from your own history, or a public one, and try to rebuild its timeline using only what your logging pipeline holds today. Time yourself. Every question you can’t answer, or that takes an hour of joining CSV exports, is a concrete gap with a concrete fix. Repeat it every quarter, since logging coverage quietly decays as services get added.
The next part of this series turns these events into detections that are written, reviewed and tested like code.
Other parts: Part 2: Writing detections as code: Sigma rules tested against real logs. Part 3: Alert fatigue: tuning detections without going blind.
Leave a Reply
You must be logged in to post a comment.